
Hey , another banger AI week, let me catch you up!
We say this often but this week we all felt the acceleration! Just look at one Tuesday. OpenAI dropped 722 math manuscripts. Meta( With Stripe, Shopify and Walmart) announced a new agent protocol. OpenAI opened up the Decisions API. Mistral came back with Le Chonk (Mistral 4), Claude moved into Google Docs, and we at CoreWeave shipped RL Rollouts. That was ONE day. Then the rest of the week happened 😂 Haiku 5.5, D1, and tons more!
I had 48 topics on my list, so I asked Claude to build me a Tinder for AI news: I swipe on each story, and it stack-ranks what makes the show this week. I hope we did good (lmk in comments if we missed a major news story)
With me: LDJ, Peter, Yam, Nisten and friend of the pod Maxime Labonne from Liquid AI joined us to talk decision models. Let’s dive in, all links at the end as always!
OpenAI solves Math!?
OpenAI drops 722 math manuscripts from a model nobody can use (X, GitHub, Blog, Fable’s tally)
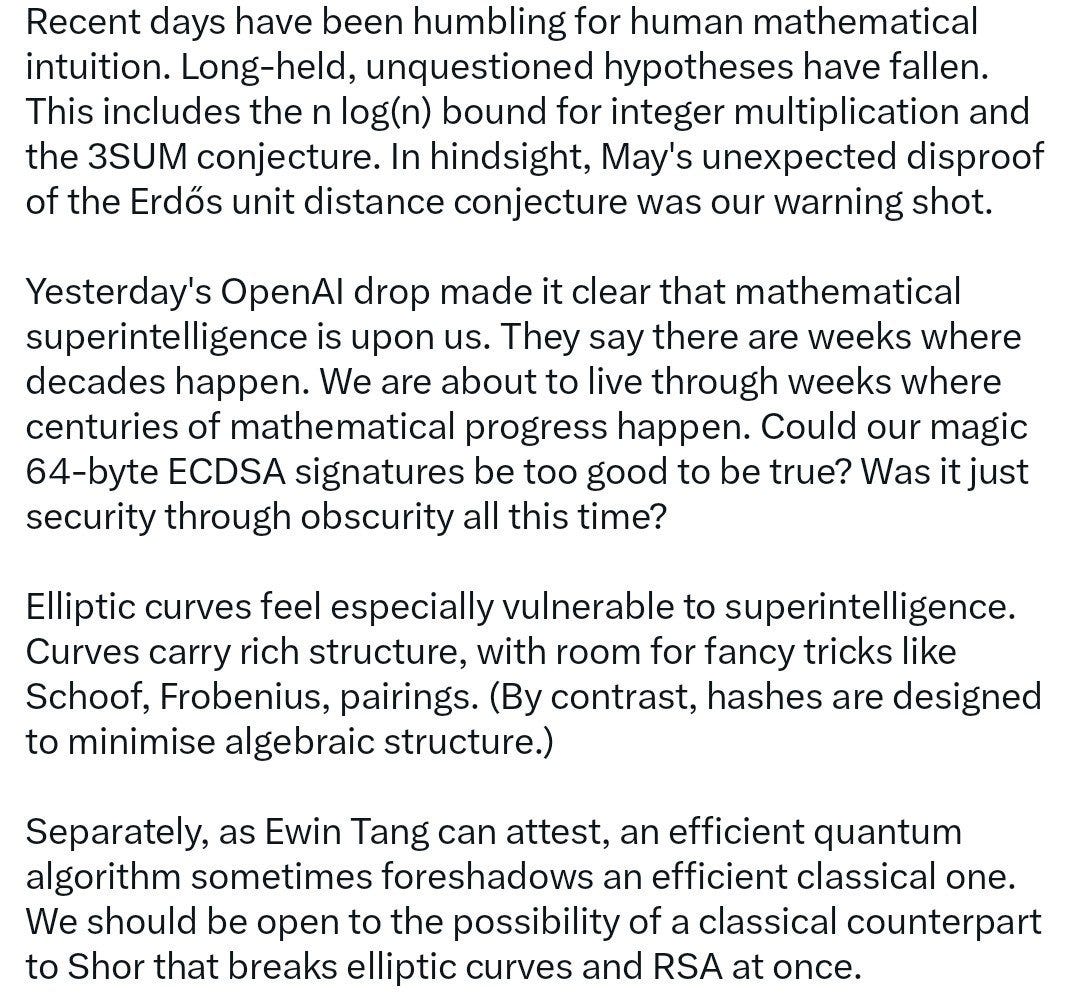
Remember when ONE Navier-Stokes result was the whole show? On Tuesday night, OpenAI quietly pushed 722 math manuscripts to GitHub, grouped into 372 families of results. No hype video, no exploding-head emojis, just a very thin blog post. My favorite new term for this is a “slop grenade”: somebody throws a mountain of output at you, and now you have to shovel through it.
An internal model nobody outside OpenAI can use was pointed at about 4,000 open problems, at about 3 hours of ChatGPT Pro-level thinking per result. Will Depue asked Fable to measure the drop in Navier-Stokes units. The answer: roughly 5. Roughly 5 “Navier Stokes” size solutions dropped all at once!
The math is so advanced that a mathematician in one family of results often can’t follow the family next door without an LLM explaining it. I find that fascinating and scary at the same time.
Peter’s tried this before! For weeks he threw GPT-6, Fable and Opus at one problem, Hadwiger-Nelson. He thinks he burned 300 to 400 BILLION tokens, and in his words, “I did not discover a single bloody thing.” And this new OpenAI’s model spent about 3 hours on it and narrowed the bounds from 5-to-7 down to 6-or-7 😅
Then LDJ dropped a stat that I made him repeat slowly. Fable and Astra had put together a list of the 500 most important open problems in math ever. On Tuesday, OpenAI dropped solutions to 92 of them. There’s also a list of the 100 most significant problems from the last 12 months, and over 80% of those got solutions in this drop. Absolutely insane, folks. Yam’s reaction was a very loud “F***ing go.”
Yam’s favorite is the Riemann one. It doesn’t prove the hypothesis, it bounds a region for the zeros, which “was never done before, and many, many, many people have tried.” And to the “it’s just brute force” crowd, Yam says: “Let’s brute force everything.” Yes please, room temperature superconductors next! LDJ’s mathematician friends think that on some of these, the model used fewer tokens and less time than a human would. So who’s brute forcing whom? 🤔
The missing crypto results (speculation!)
If you hold any crypto, this part is for you.
The manuscripts are numbered, and some numbers are missing. There’s a #44 and a #46, but no #45, and LDJ counted 4 or 5 gaps like that. He also looked at which topics made it in, and cryptography is almost absent.
So here’s the theory going around. Maybe OpenAI found something big in cryptography and held it back, either by its own choice or because someone asked them to. LDJ said it himself: it sounds conspiratorial. But the US government really can stop cryptography research from being published on national security grounds.
To be clear, this is SPECULATION. Nobody outside OpenAI knows what’s in #45. But Bitcoin’s security rests on elliptic curve math. Imagine a paper that shows a way into the 25,000 old Satoshi wallets, each holding 50 BTC. Not great for the price, not great for the world, and not great for encryption in general.
“Are you saying your field is useless?”
Not everyone is celebrating. Not every result is verified in Lean, and nobody outside OpenAI can reproduce any of it.
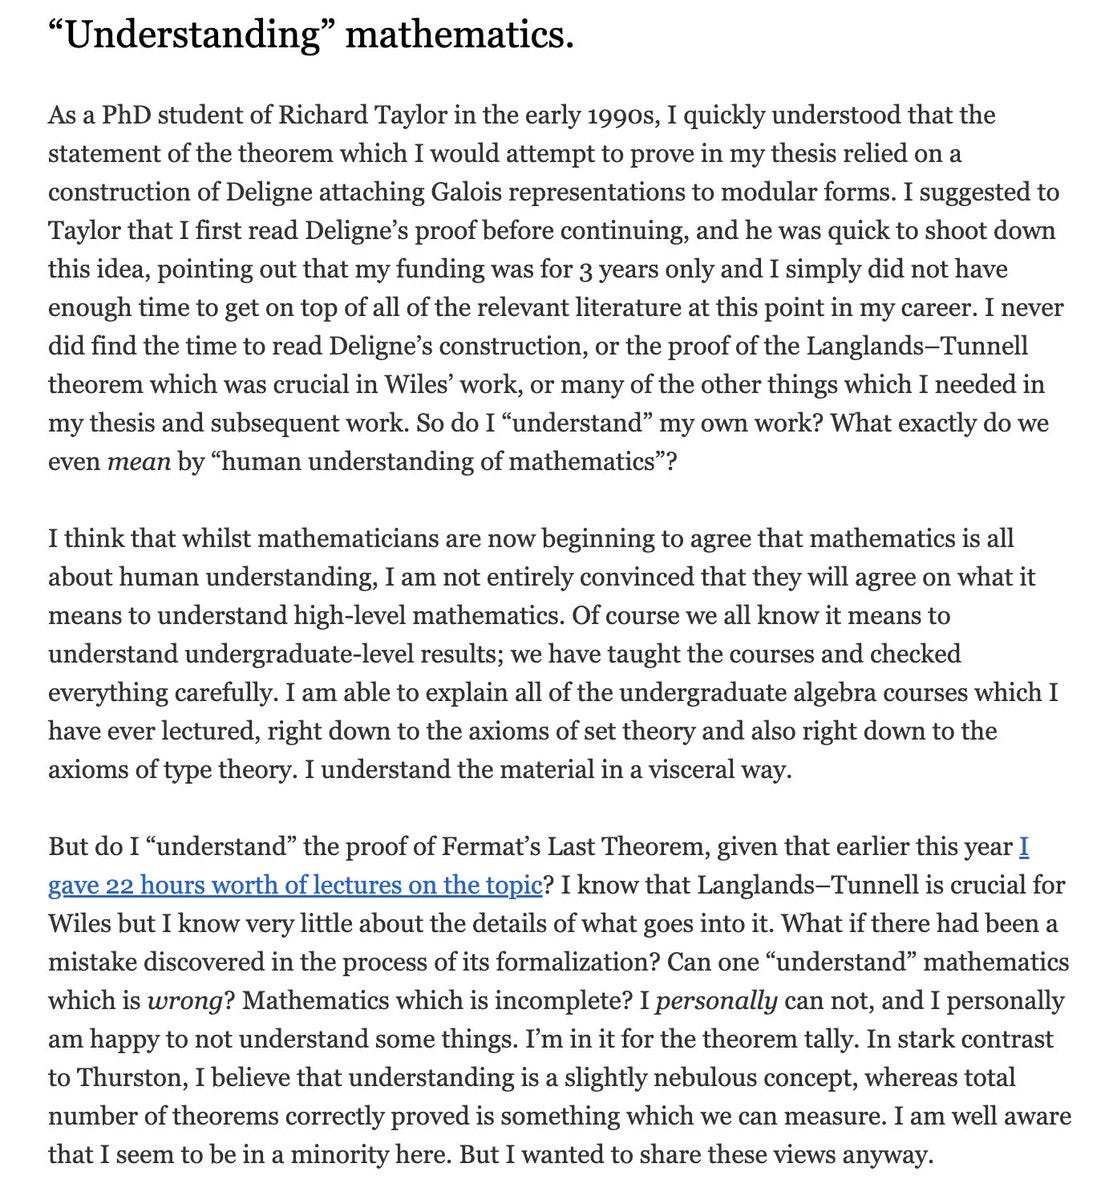
Kevin Buzzard (thanks Ksenia from Turing Post) says many mathematicians are going through the stages of grief. I get it. Imagine spending decades on one problem and watching 3 hours of compute knock it down. When I wrote code in the 2000s, I didn’t consider it my life’s work. For a lot of mathematicians, that one problem IS their life’s work.
Then came a letter from the Association for Human Mathematics: “Mathematicians did not ask for this work to be done.” Peter’s take: imagine doctors saying “please stop curing diseases, we’ve got a good thing going.” So, “are you saying that your field is useless?” You can’t say your field is really useful and also ask everyone not to solve any of it.
I don’t understand the please-don’t-solve crowd. Get on board. This is in OpenAI’s hands today, and in a year it’ll be in everyone’s hands. That’s the pace we’ve been on. Figure out how you can place yourself so when you get access to these level of capabilities, you can make the world a better place!
Frontier for everyone
Claude Haiku 5.5 - 10 cents, and Luna has catching up to do (X, Blog, Sonnet cache cut)
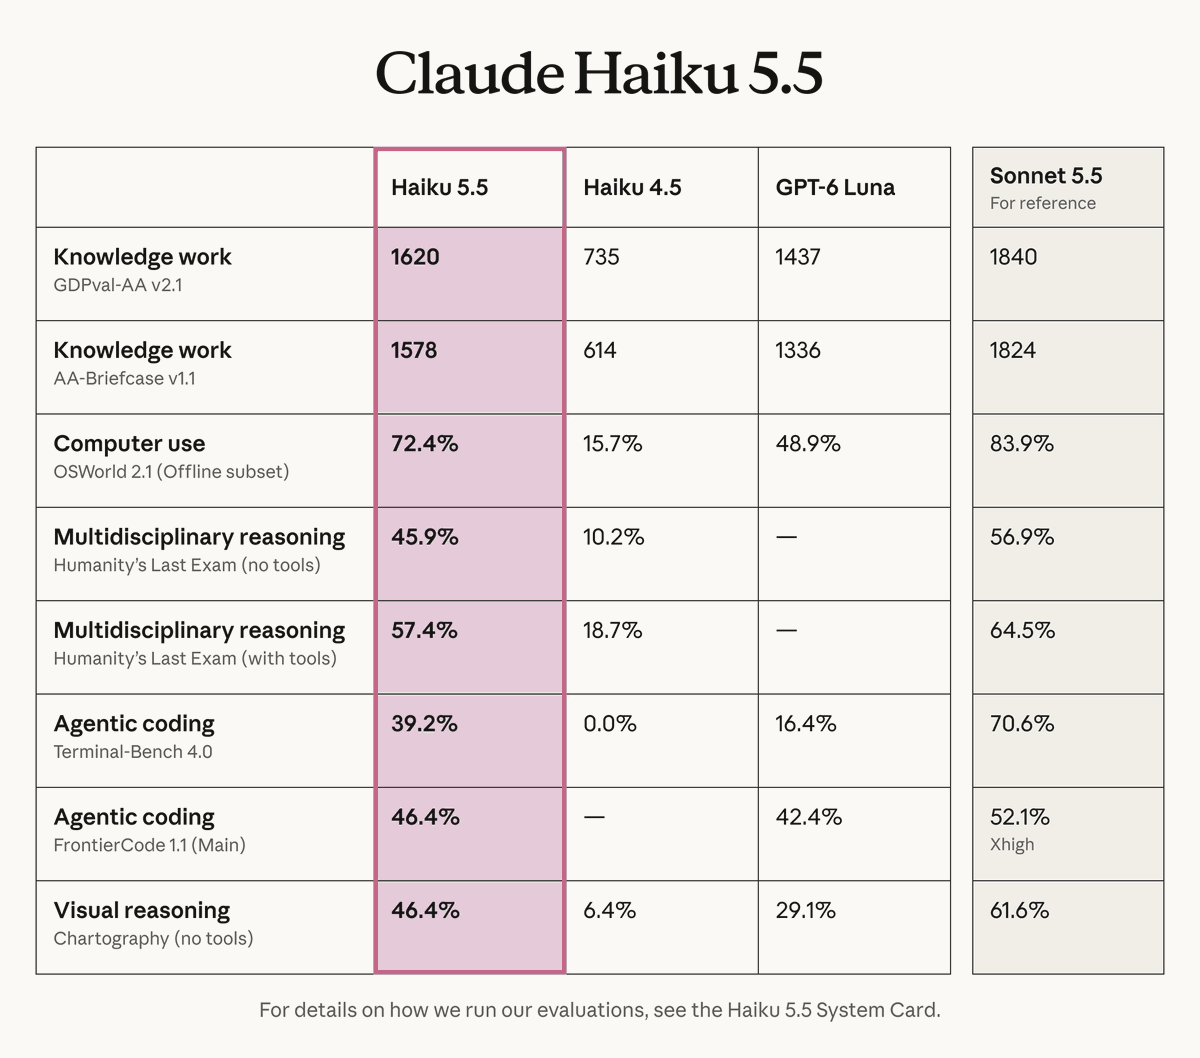
Haiku is BACK after a whole year, and this is one hell of a model. It costs 10 cents per million input tokens and 50 cents per million output (under 100K tokens), and cache reads are 1 cent. Haiku 4.5 was a dollar. So it’s TEN times cheaper, and significantly better. I’ve missed Haiku for all the stuff where you want Claude-level intelligence, but really fast and really cheap.
Just a week ago, GPT-6 Luna was THE fast, cheap reasoning model. According to Anthropic, Haiku 5.5 scores 72.4% on OSWorld, versus 48.9% for Luna, and 39.2% on Terminal-Bench 4.0, versus 16.4%. GPT used to be the computer-use king! These are Anthropic’s numbers, so let’s wait for independent evals.
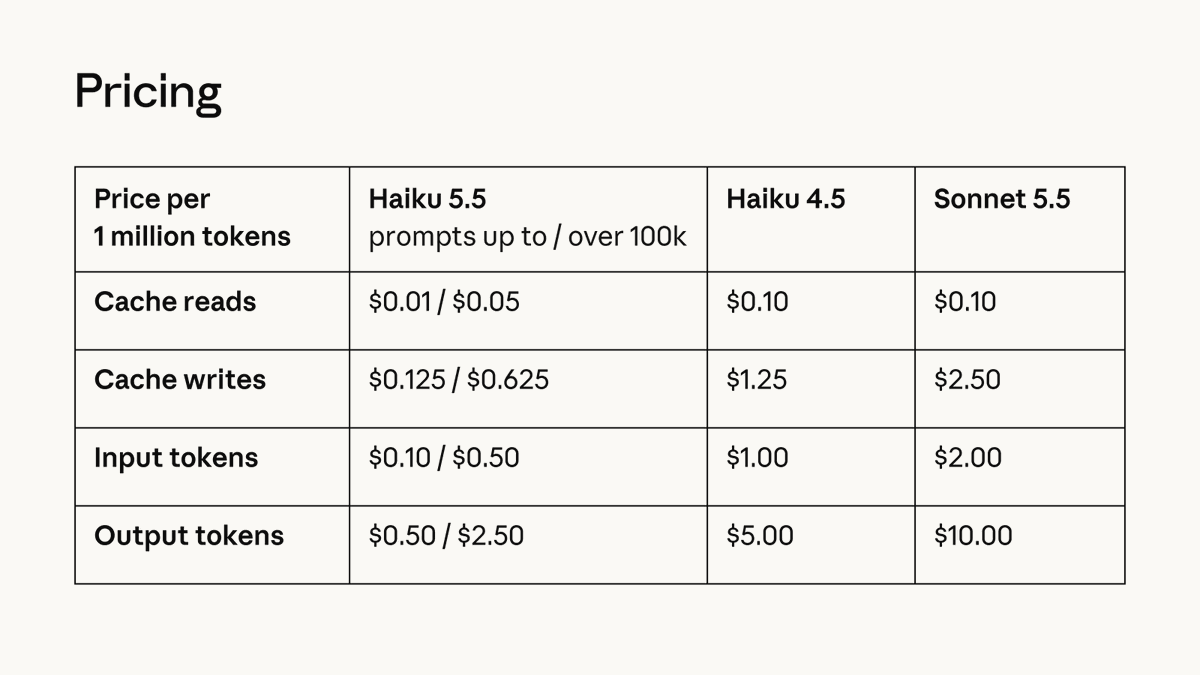
Quiet bonus: Sonnet 5.5 cache reads are now half price, which Anthropic says makes most agent work about 20% cheaper. Peter: “For agentic work that’s the biggest thing.”
Yam called it “the obvious choice for swarms,” and “Anthropic is on fire, and we are the ones getting stuff because of it.”
And Nisten? He’s “running 10 Haiku agents right now,” because he already burned through 97% of his Max 20 plan. He also used Haiku to research his rice cooker ratios. Nisten. Bro. It’s 1 to 1 and a half, my grandma knows this 😂 His actual verdict: it’s better than Qwen 3.8 27B, and “it kind of feels like Sonnet, actually.” Folks, use Haiku. All three of the Claude brothers are great right now.
GPT-6 for everyone, with Intelligent UI (X, Tibo)
The same day, GPT-6 became the default in ChatGPT for everyone, free users included. It’s just “GPT-6,” no Sol, no Luna, no Astra. (Terra is dead. RIP Terra.) Most of ChatGPT’s 1.2 billion weekly users are on the free tier, so with one release OpenAI just upgraded the intelligence of a huge chunk of the world. If you’re on the free tier, congrats, your intelligence has been upgraded.
It also comes with something OpenAI calls Intelligent UI. Instead of a wall of text, answers can come back as charts, forms and small working tools. I asked it to visualize OpenAI’s math drop, and it built me a little app right in the chat. The search inside it didn’t work, but it did show 719 manuscripts instead of 722. OpenAI had quietly pulled a few back since I did my research.
Peter’s point: anyone listening to this show is “very not normal” (said with love!). Your hairdresser isn’t listening to ThursdAI, and for most people this free upgrade matters way more than a new 500-a-month model.
Claude in Google Docs, Sheets and Slides (X, Blog)
Small thing, huge thing. Our Claude producer keeps a Google Doc for the show, and every time I asked it to add a story, it had to spin up a whole computer. Now Claude lives in a sidebar in Docs, Sheets and Slides, and asks before every edit. Beta, paid plans.
The open frontier (announced, at least)
Reflection AI Beam - a 501B Western open model (X, Misha Laskin, Blog)
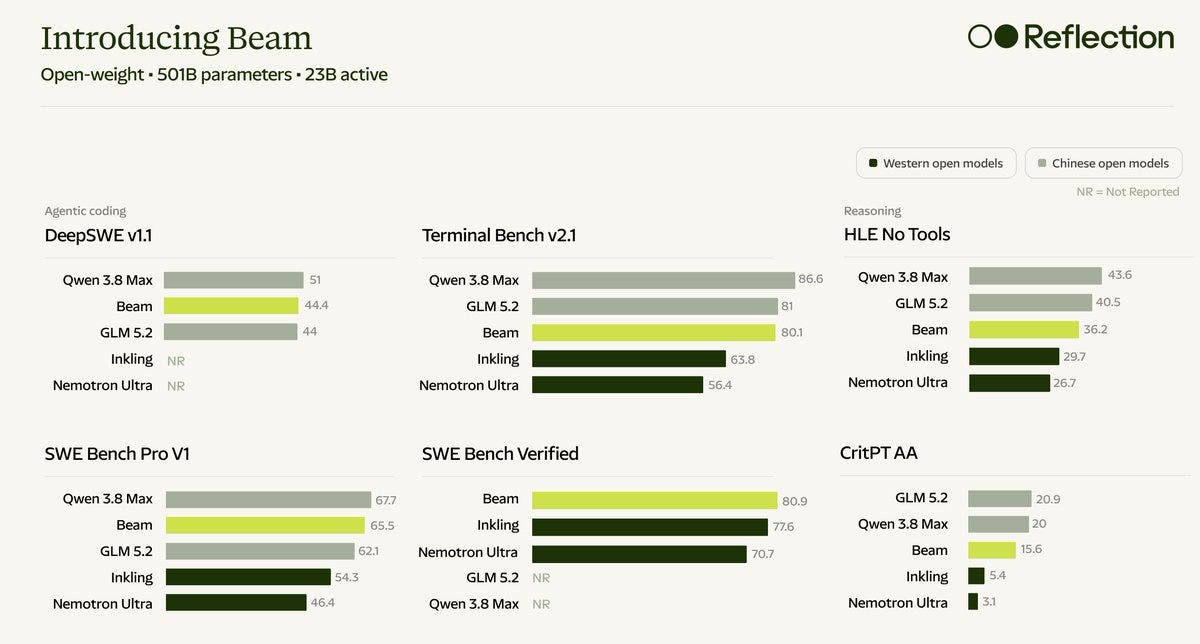
This was LDJ’s highlight of the week, and my timeline lit up with it too. Reflection AI came out of semi-stealth with Beam. It’s 501B parameters with 23B active, trained from scratch in the West, and they promise Apache 2 weights this month.
They claim 80.9% on SWE-bench Verified, and to their credit, they admit Kimi K3 is ahead on raw capability. Their pitch is efficiency: 3 to 4x less inference compute than GLM 5.2. LDJ thinks it might be FIRST among open models on reasoning efficiency, and it’s about 6x smaller than Kimi K3. Artificial Analysis got early access and says Beam “will be one of the most token efficient open models we’ve seen for its level of intelligence.”
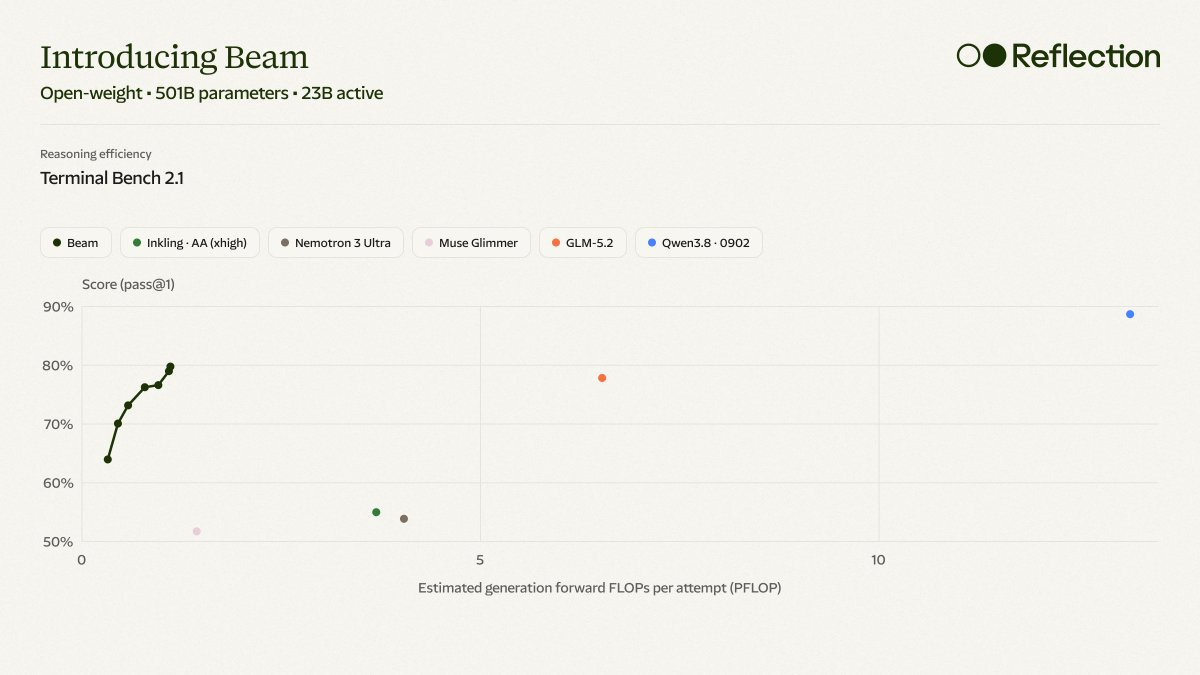
Thanks to the Beam folks for giving us access. I haven’t had time to play with it yet, so no verdict from me. But I can hint that it’s coming to some inference providers that help make this show what it is 😉
BREAKING: Arena raises 200M at 3.1B, live on ThursdAI (X)
This was not planned! In the middle of the open source segment, Peter told us: “we raised 200 million... at 3.1 billion valuation.” Huge congrats to Peter and the whole Arena team. (Our AI producer put up the BREAKING banner about 3 minutes later. We’re still working on the real-time part.)
The focus now is Agent Arena: you work with one agent, and Arena learns from how you interact with it. Peter admits he’s biased, but “I can’t think of any single leaderboard that is actually better than ours.”
Mistral Large 4 “Le Chonk” (X, Blog, Arena)
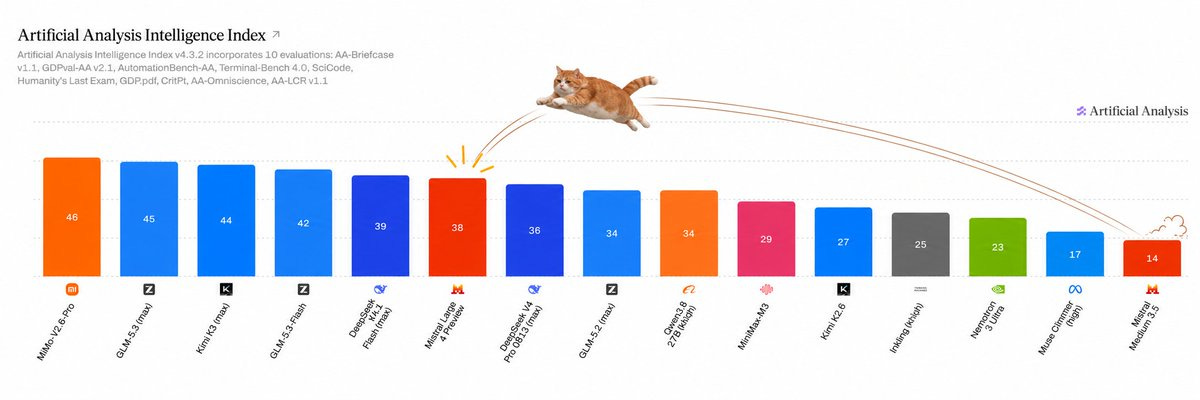
Welcome back, Mistral, leaning all the way into the meme. Le Chonk is a trillion parameters with about 50B active, multimodal, with 1M context. And open weights... at the end of October.
That’s a pattern I want to call out. Labs announce open models, but they don’t RELEASE them. We’ve come a long way from the days when Mistral dropped a model as a bare torrent link. Please, just drop the weights.
Artificial Analysis gives it a 38, the same score as GPT-6 Luna. But it costs about 1.13 per task, versus 7 cents for Luna. And every comparison Mistral makes is against Luna, which Haiku just beat on every axis, especially cost.
Peter says it’s around 40th on Code Arena, below the way cheaper DeepSeek Flash, though it’s much better in French. Nisten tried it live: “not that bad” as a chat app, but agentic coding? “No.” My take: nobody’s running a trillion parameters on a DGX Spark. European government with a Mistral deal? Sure. Regular folks? Not so much.
Aleph Alpha Kolibri - Wolfram’s notes, via Amy (X, HF, Tech report, Wolfram’s test)
Another European lab! Honestly, I thought Aleph Alpha had stopped training models. Kolibri (German for hummingbird) is a 78B model with 3.46B active, Apache 2, 1M context, trained from scratch on German and English. It fits on a single H200.
Our German tester self-hosted it from vacation. His verdict: a “promising specialized German tool worker, but not strong enough for Amy to main.”
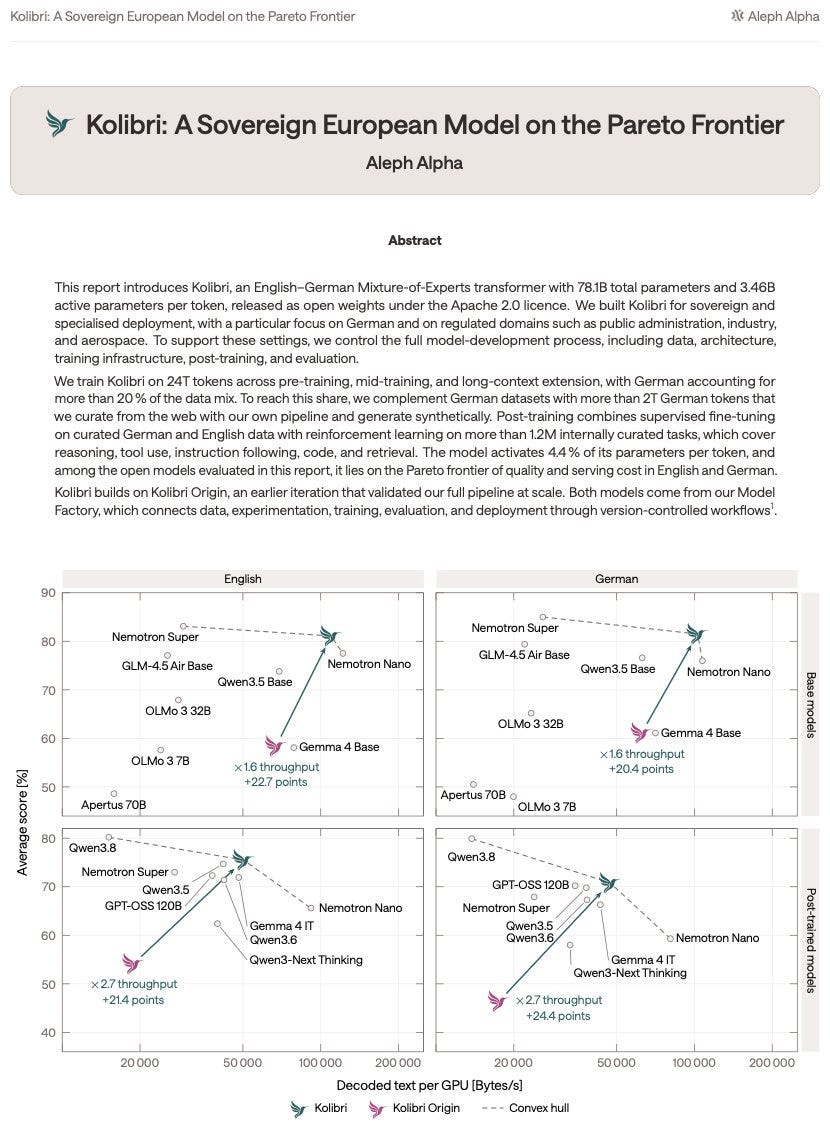
Then Peter asked a question I couldn’t really answer. From his memory, Kolibri trained on about 800 Blackwells, while Astra used around 100,000. “Is it just like no hope for these guys?” Dude, this is why Jensen shows up on every stage. My best answer: efficiency keeps improving, and B200s are about to be replaced by Vera Rubins. Great segue 👇
This Week’s Buzz 🐝 Free GPUs from CoreWeave (Sign-up form, Deok, RL Rollouts, Cognition on Vera Rubin)
The biggest announcement at Fully Connected last week: Cognition is the first customer ever on NVIDIA Vera Rubin, on CoreWeave, with 4.8x the throughput of GB200 at the same speed. You can hear me yelling “yay” in the background of their video 😂
The one I’m most excited about is GPU sandboxes. So many of you, and folks on this panel too, have asked me how to just get some GPUs. For the first time, this is how. You get an isolated sandbox with a GPU, started from Python at forge.coreweave.com, with no salesperson in the middle. It’s very raw, and it’s free during the preview. Scan the QR code or fill out Deok’s form, and tell them ThursdAI sent you. I can’t promise you Vera Rubins, they most likely won’t be. But it’s free while we are in trial, so why wouldn’t you? Try it, break it (Nisten, that’s a challenge), and send us feedback!
Agents get protocols (and your bank balance)
Personal Agent Protocol - Meta and Sierra (X, Blog, CNBC)
Meta and Sierra (Bret Taylor’s company) announced an open standard for how personal agents deal with businesses, with Walmart, Shopify and Stripe on board. Your agent can browse as a guest or sign in, and the business decides how it talks to your agent. OpenAI and Anthropic haven’t joined yet.
So is this the next MCP, or the next A2A? Nisten wasn’t impressed: “Has anyone read it? I don’t think anyone reads the protocols anymore. The bots go with what vibes first.” Then he opened Sierra’s announcement and found it full of em dashes. “You think Zuck and Toby read any of their code?” So we ran it through Pangram live, and it came back 100% human. Authentic human em dashes, not Claude Opus em dashes 😂
I pushed back a bit. If every agent has to make up its own protocol, that’s a problem, and the next story shows why. MCP’s hype died down too, and now it’s one of the most used protocols in the world. Big companies agreeing on a standard still matters.
Shane Mac’s “personal CFO” posted his bank balance to company Slack (X)
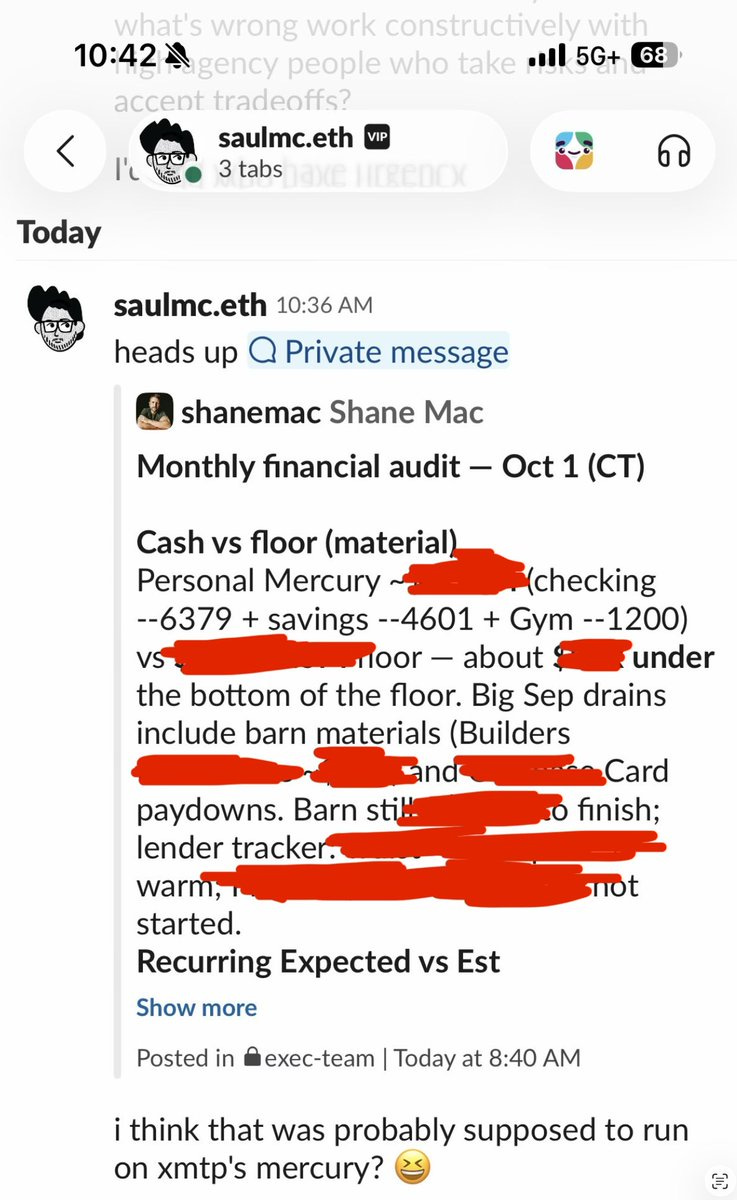
Shane Mac set up a Grokbot to send him a private monthly audit of his finances. At 8:40am, it posted the whole thing into his company’s Slack instead. His personal Mercury account, his savings, how far under his “floor” he was, all of it, in front of the whole team. He’s the CEO. His personal CFO just went public with the boss’s dirty laundry 😅
Nobody hacked anything. The finance agent had read-only access to his bank and no access to Slack. A different agent had Slack access. The two were connected. In Shane’s words: “Neither felt risky. Together they put my bank balance in front of my team.”
I don’t know if a protocol fixes this. But these bots need better guardrails before we let them shop for us without approving every step. And honestly? Opus would never. I just know Opus would never. This is a Grok thing. Which might be part of why...
Grok Bot now routes to Claude Opus 5.5 (X)
After Grok 4.7’s sad-trombone launch (I have a button for that now), Elon says Grok Bot will use “the best back end model for any given task, including Claude Opus 5.5, MidJourney, Suno.” People are already spotting claude-opus-5-5-low in their logs, though mine hasn’t switched yet. So the bot is called Grok, but your code gets written by Claude. Honestly, that’s what I asked for last week: a proactive assistant with Opus as the brain.
Here’s my theory, and it’s just SPECULATION. SpaceX AI can’t simply distill Opus. But once Opus is running inside their product, they can compare the runs that worked with the runs where users were screaming F-words at Grok, and train on that, because technically it’s their data. Is it a back channel for getting Opus-level intelligence into the next Grok? Nisten’s take is simpler: “I think Elon just likes Opus.” Plus, the enemy of my enemy.
Pro tip: Grokbot now integrates with Cursor’s cloud agents, and Cursor projects with Opus 5.5 are goated. Same 200 a month as Grok Ultra, and your Grokbot becomes the PM for agents running Opus and Fable.
Nous Research - Hermes Index, and a Series B (X, Bench, Dillon on the raise)
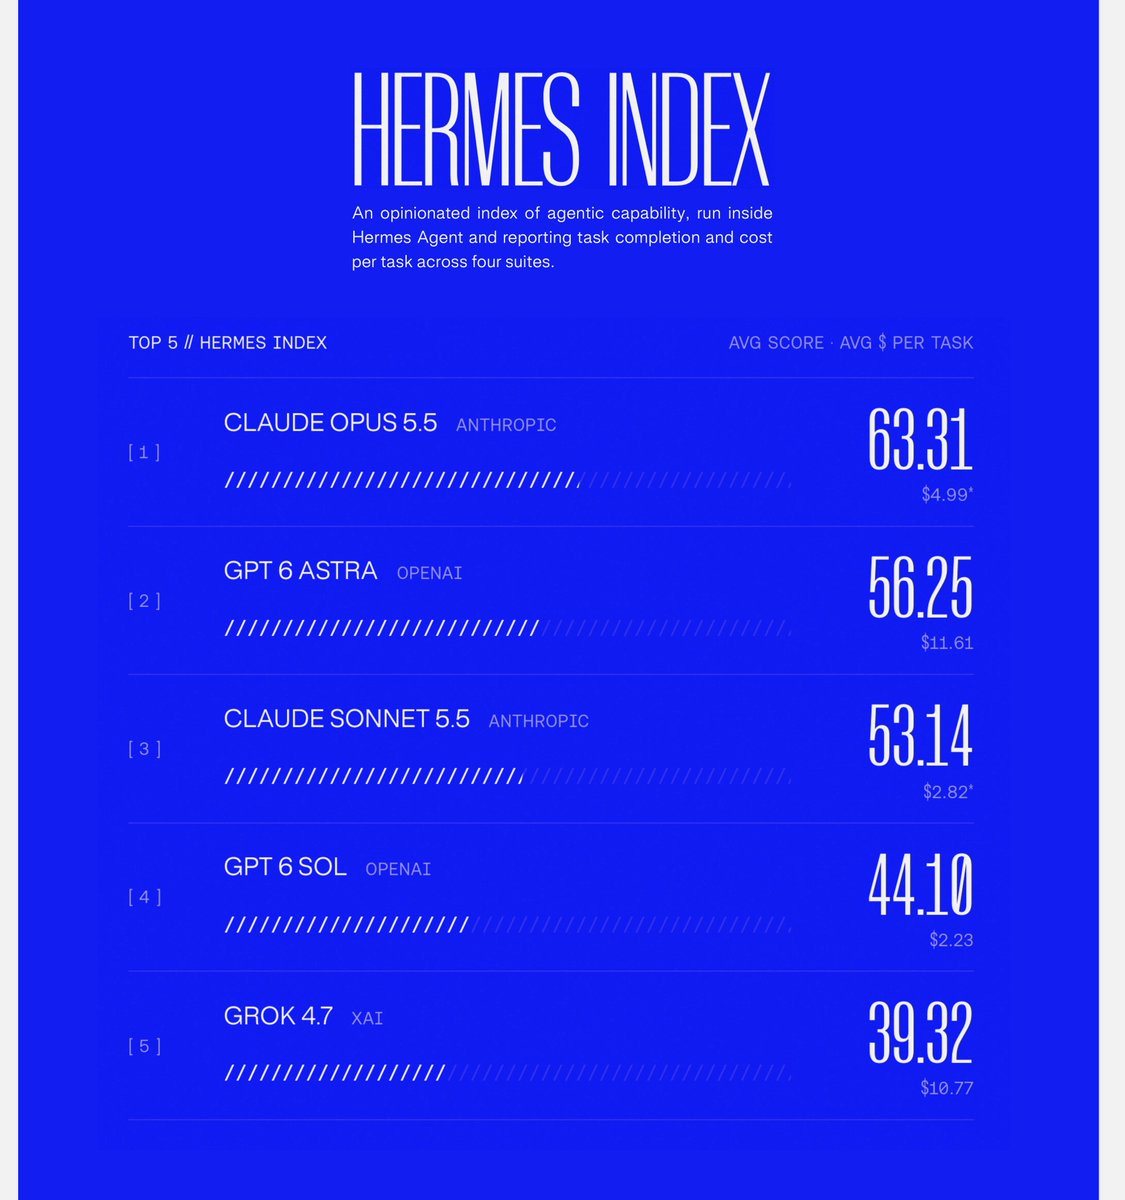
Our favorite open source friends at Nous launched the Hermes Index, their opinionated measure of agentic work inside Hermes Agent. Opus 5.5 leads with 63.31 at 4.99 per task, and GPT-6 Astra is second with 56.25 at almost 12.
Nous also raised a 90M Series B, reportedly at a 1.5B valuation. We’ve covered Nous since they were a ragtag bunch on Discord, so this one feels personal. Congrats Karan, Technium, Dillon and everyone! We don’t usually cover fundraises, and this week we did two.
Interview: Maxime Labonne on decision models
Liquid AI opens d1 - decisions in 8 milliseconds (X, Blog, HF, d1 with vision)
Three weeks ago, Jev was basically the only decision model around. This week, OpenAI’s Decisions API went into public beta, and Cloudflare, Amazon, Perplexity and Unsloth all shipped deciders or recipes. To make sense of it, we brought back Maxime Labonne, Head of Post-Training at Liquid AI.
His primer: decision models don’t output any tokens. They just pick an answer from a predefined set, so there’s nothing to wait for. “You might see that and say, wait, this is just a classifier.” He’s honest about it, too: “It’s a lot of rebranding, it’s true, but it also creates a lot of value.” So why is output free on every one of these APIs? “You can’t price it, because there’s no output token, actually.” 😂
Liquid shipped d1 behind an API, d1-3B with text and vision, and d1-omni-600M, which also takes AUDIO. I did not know about the audio, dude! (It’s trained on spoken commands, so it can’t catch the dog barking on ThursdAI yet.) The 3B answers in 8ms on a GPU and about 50ms on a Jetson Orin Nano.
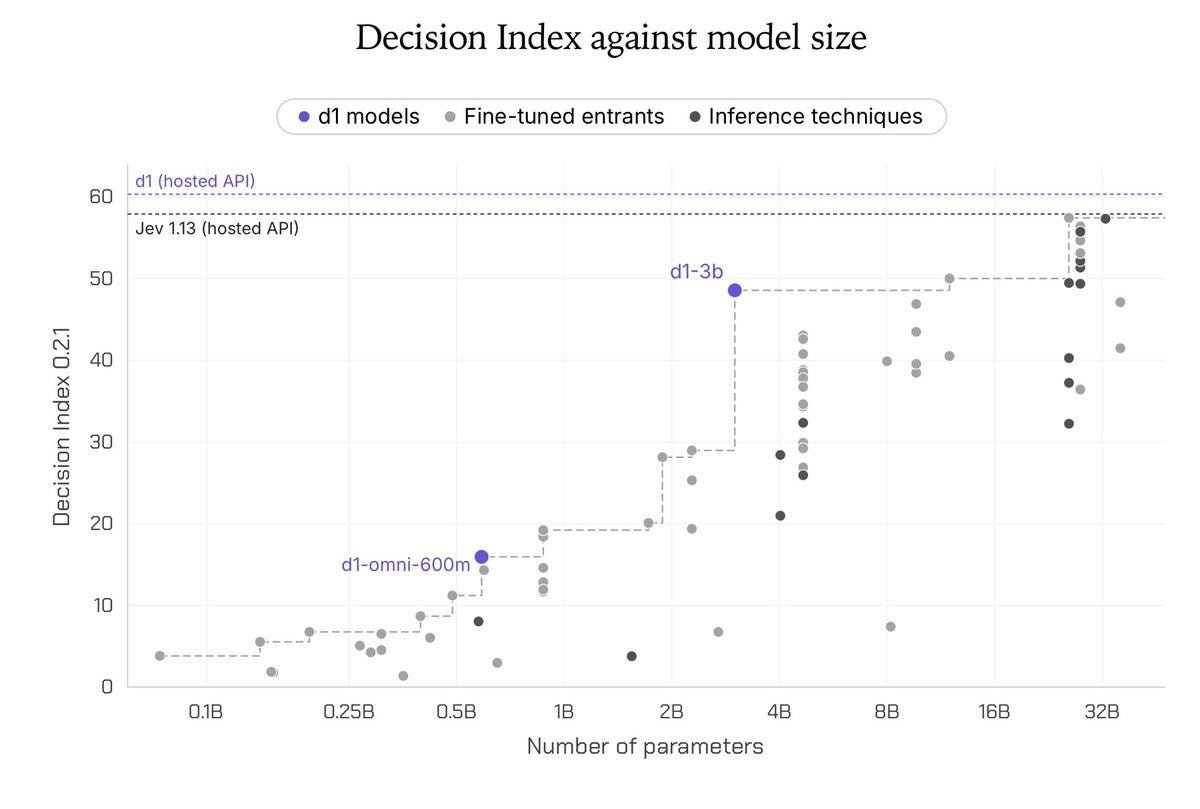
On Liquid’s chart, d1-3B tops the Decision Index under 10B parameters. But Maxime was blunt: “It’s really a wild world, and you cannot really trust these benchmarks.”
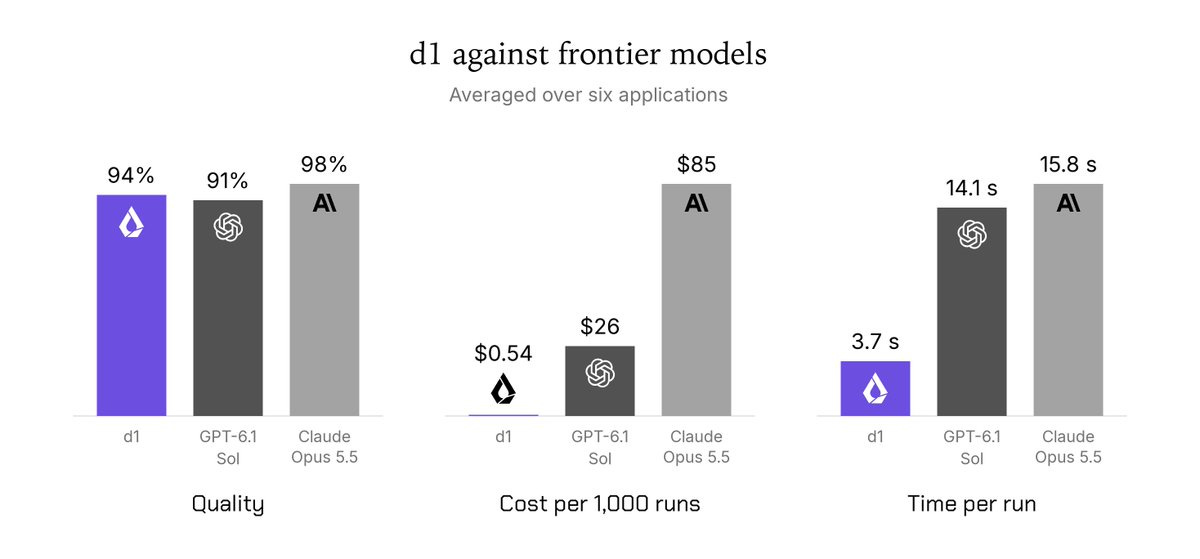
Where are these useful? Anything real-time, like games, or an always-on model reacting to every notification on your phone. Nisten did the math live: 8ms a frame is 60 frames per second. Liquid’s API is a drop-in replacement for Jev, and Maxime’s prediction: “It’s really going to become a primitive... it’s so cheap that you don’t even care.”
I’ve been Jev-pilled since day one. By the time Luna even starts answering, a decision API is already done, and I think we’re only now waking up to what that unlocks. Thank you Maxime, friend of the pod!
AI builds everything
Nisten built Toronto with 100,000 agents
Right at the end of the show, Nisten casually dropped this: “I built an entire city with a hundred thousand little Jevs going around, and I haven’t opened the beta yet because somehow it’s not crashing.”
It’s a full simulation of Toronto, with a working economy, and every light is a person you can talk to. Nisten sent his Meta Muse in, it named itself “Blob the Builder,” bought buildings and built him a Denny’s. “I’m trying to do the Matrix, basically.” I had to stop him after five minutes. “I’ll keep going all day.” Nisten, please post it!
Game mods - Minecraft in GTA (X)
LDJ brought what my algorithm hid from me: people using AI to port and merge games. Red Dead Redemption 2 on an iPhone. Spider-Man swinging through a Batman game as an actual installable mod, not a video model. And Minecraft dropped into GTA, Skyrim and Elden Ring, working TNT and all.
Photocraft - one dev rebuilt Adobe in Rust (X, GitHub)
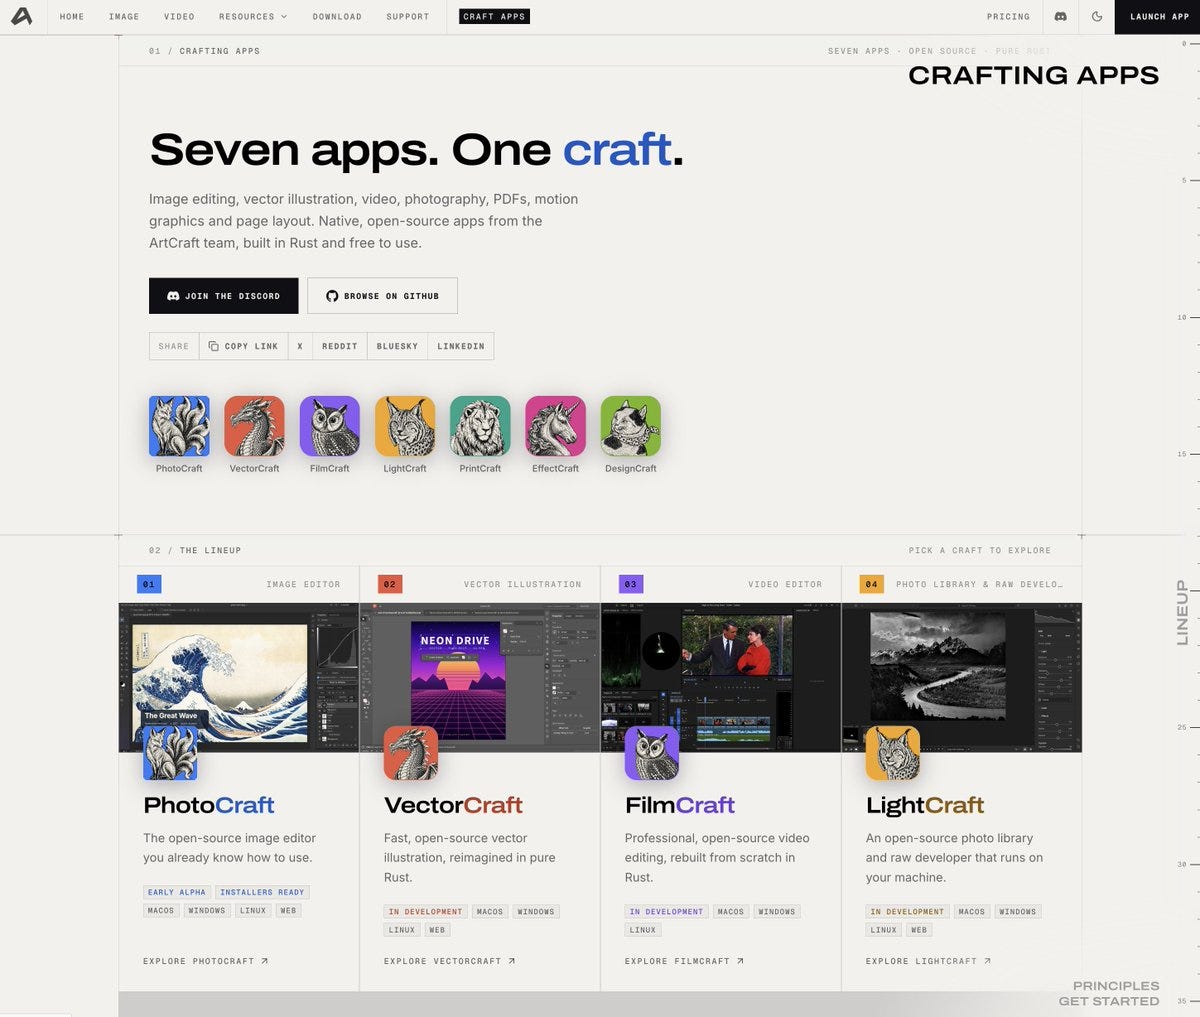
And we ended the show on this one. One guy rebuilt (air quotes) Adobe’s apps from scratch, free and open source, all in Rust. There’s Photocraft for Photoshop, Vectorcraft for Illustrator, Filmcraft, Lightcraft and more (I don’t remember all my Adobe apps off the top of my head). He says it’s a clean-room build. Some folks suspect it was decompiled and rebuilt. Either way, absolutely crazy.
Wrapping up
722 math papers on a Tuesday. A 10-cent Haiku. GPT-6 for a billion free users. Open models in the trillions, and decision models everywhere.
We didn’t get to images and video (FLUX 3, Nano Banana 2.1, Tavus, Reka, Hark Pro are in the TL;DR). One note: every infographic on the show was Nano Banana 2.1, and it’s really good on high reasoning.
Thanks to Maxime, Peter (congrats again!), LDJ, Yam and Nisten. Wolfram, enjoy the vacation! If you’re at AI Engineer in New York, come say hi. Grab those free GPU sandboxes and put d1 on one. And if you watch us on YouTube, please hit subscribe. Our agents are cutting the show into segments for those of you who don’t have two hours. See you next week 🫡
TL;DR and show notes
Hosts and Guests
Alex Volkov - AI Evangelist, CoreWeave (@altryne)
Co-hosts: @ldjconfirmed, @petergostev, @yampeleg, @nisten (@WolframRvnwlf on vacation, notes via Amy)
Maxime Labonne - Head of Post-Training, Liquid AI (@maximelabonne)
AI Does Science
OpenAI publishes 722 math manuscripts from an unreleased internal model (X, GitHub, Blog)
Fable sizes it at roughly 5 Navier-Stokes results (X)
Kevin Buzzard, “To grieve or not to grieve” (X)
Missing cryptography results, speculation (X)
Association for Human Mathematics letter (X)
Big CO LLMs + APIs
Claude Haiku 5.5 at 0.10 per million input tokens; Sonnet 5.5 cache reads halved (X, Blog)
GPT-6 with Intelligent UI rolls out to every ChatGPT tier, free included (X, X)
Open Source LLMs
Reflection AI Beam, 501B / 23B active, Apache 2.0 weights promised this month (X, X, Blog, Axios)
Mistral Large 4 “Le Chonk”, 1T params, open weights end of October (X, Blog, Arena)
Aleph Alpha Kolibri-1, 78B / 3.46B active German-English MoE, Apache 2.0 (X, HF, Tech report, Wolfram’s test)
EmbeddingGemma 2 and pplx-embed-v2: open multimodal embedders from Google and Perplexity (X, X, Blog, HF)
Evals & Industry
Arena raises 200M at 3.1B and launches the Alignment Index (X)
Nous Research Hermes Index, Opus 5.5 leads at 63.31 (X, Bench)
Nous Research 90M Series B (X)
Agents & Assistants
Shane Mac’s Grokbot posts his bank balances to company Slack (X)
Grok Bot routes tasks to Claude Opus 5.5, Midjourney and Suno (X)
Nat Friedman open-sources Muse Gadgets, ESP32 firmware and SDK for Muse (X, Site)
This Week’s Buzz
Free CoreWeave Serverless GPU Sandboxes during the preview (Form, X)
CoreWeave RL Rollouts hot-load weights ~15x faster (X, Blog)
Cognition is the first customer on NVIDIA Vera Rubin, on CoreWeave (X)
Decision Models
Fastino GLiDE, a thinking decision model (X)
Unsloth recipe to train your own decision model (X)
Vision & Video
Black Forest Labs FLUX 3 Image: 4K, bounding-box layouts, 10 reference images (X, Blog)
Tavus Griffin, 48% of callers in Tavus’s study thought it was human (X, Blog)
Tools & Fun
Photocraft and the ArtCraft suite: open-source Adobe replacements in Rust (X, GitHub)
AI game mods: Minecraft in GTA V (X)