

Hey, it’s Alex 👋
What a freaking week! A week after every lab head agreed to “pace the frontier”, Anthropic and OpenAI shipped big new models within hours of each other, and both of them are CHEAPER. So much for pacing 😂
And we had a new producer on the show today! Opus 5.5 listened to us live, put up the chyrons, kept me on time (mostly) and even fact-checked Nisten on air. If the stream died, you knew who to blame. You can re-watch it work on thursdai.live if you want to experience being there with us!
3 huge themes this week: pacing the frontier does not mean stopping, Assistants not just agents (Meta went all in on Muse at Connect), and voice, where Google now says it has the best TTS in the world... and it clones voices.
With me: Peter Gostev (Arena), Nisten, Yam Peleg, and Wolfram Ravenwolf live from AI Engineer Paris (thanks Mazi for the tether!), plus JevBench creator Florian S. Let’s dive in (all links at the end as always!)
Frontier AI - not pacing yet!
Claude Opus 5.5 - Opus is BACK, Fable-level smarts for 40% less (X, Blog, System card)
Folks. FOLKS. Opus 5.5 is the highlight of my week, and it’s not even close. It’s like Opus 4.6 is back, with Fable-level abilities, and it talks like a normal person again - no more Jargon Douche Claude!
My week started with burning through my quotas on Fable, and I was like, oh no, I need Claude for production on Thursday! Then Opus 5.5 dropped and... I just couldn’t get to the end of my quota. I ran workflows, agents, Claude Code for hours with no end in sight. Remember the “limitless Codex” days when you never thought about quotas? Then Astra came out and I burned my entire weekly quota in half a day (ps. this was partly due to a bad config, so if Astra is burning your tokens, keep reading for a fix). Now it’s flipped, and Claude is the seemingly limitless one. And it’s fast!
The numbers back it up. It beats Anthropic’s own Fable 5.1 on GDPval-AA (1846 vs 1735), 66.4% on Terminal-Bench 4.0 vs 57.9% for GPT-6 Astra, and it’s 40% cheaper than Opus 5. Output goes from $25 to $20 /1Mtok and cached reads from 50 cents to 20 cents, and for agentic coding the cache reads are most of your bill, so you really feel it. Basically the smaller, overachieving brother of Fable. Sonnet and Haiku 5.5 are coming in the next few weeks too.
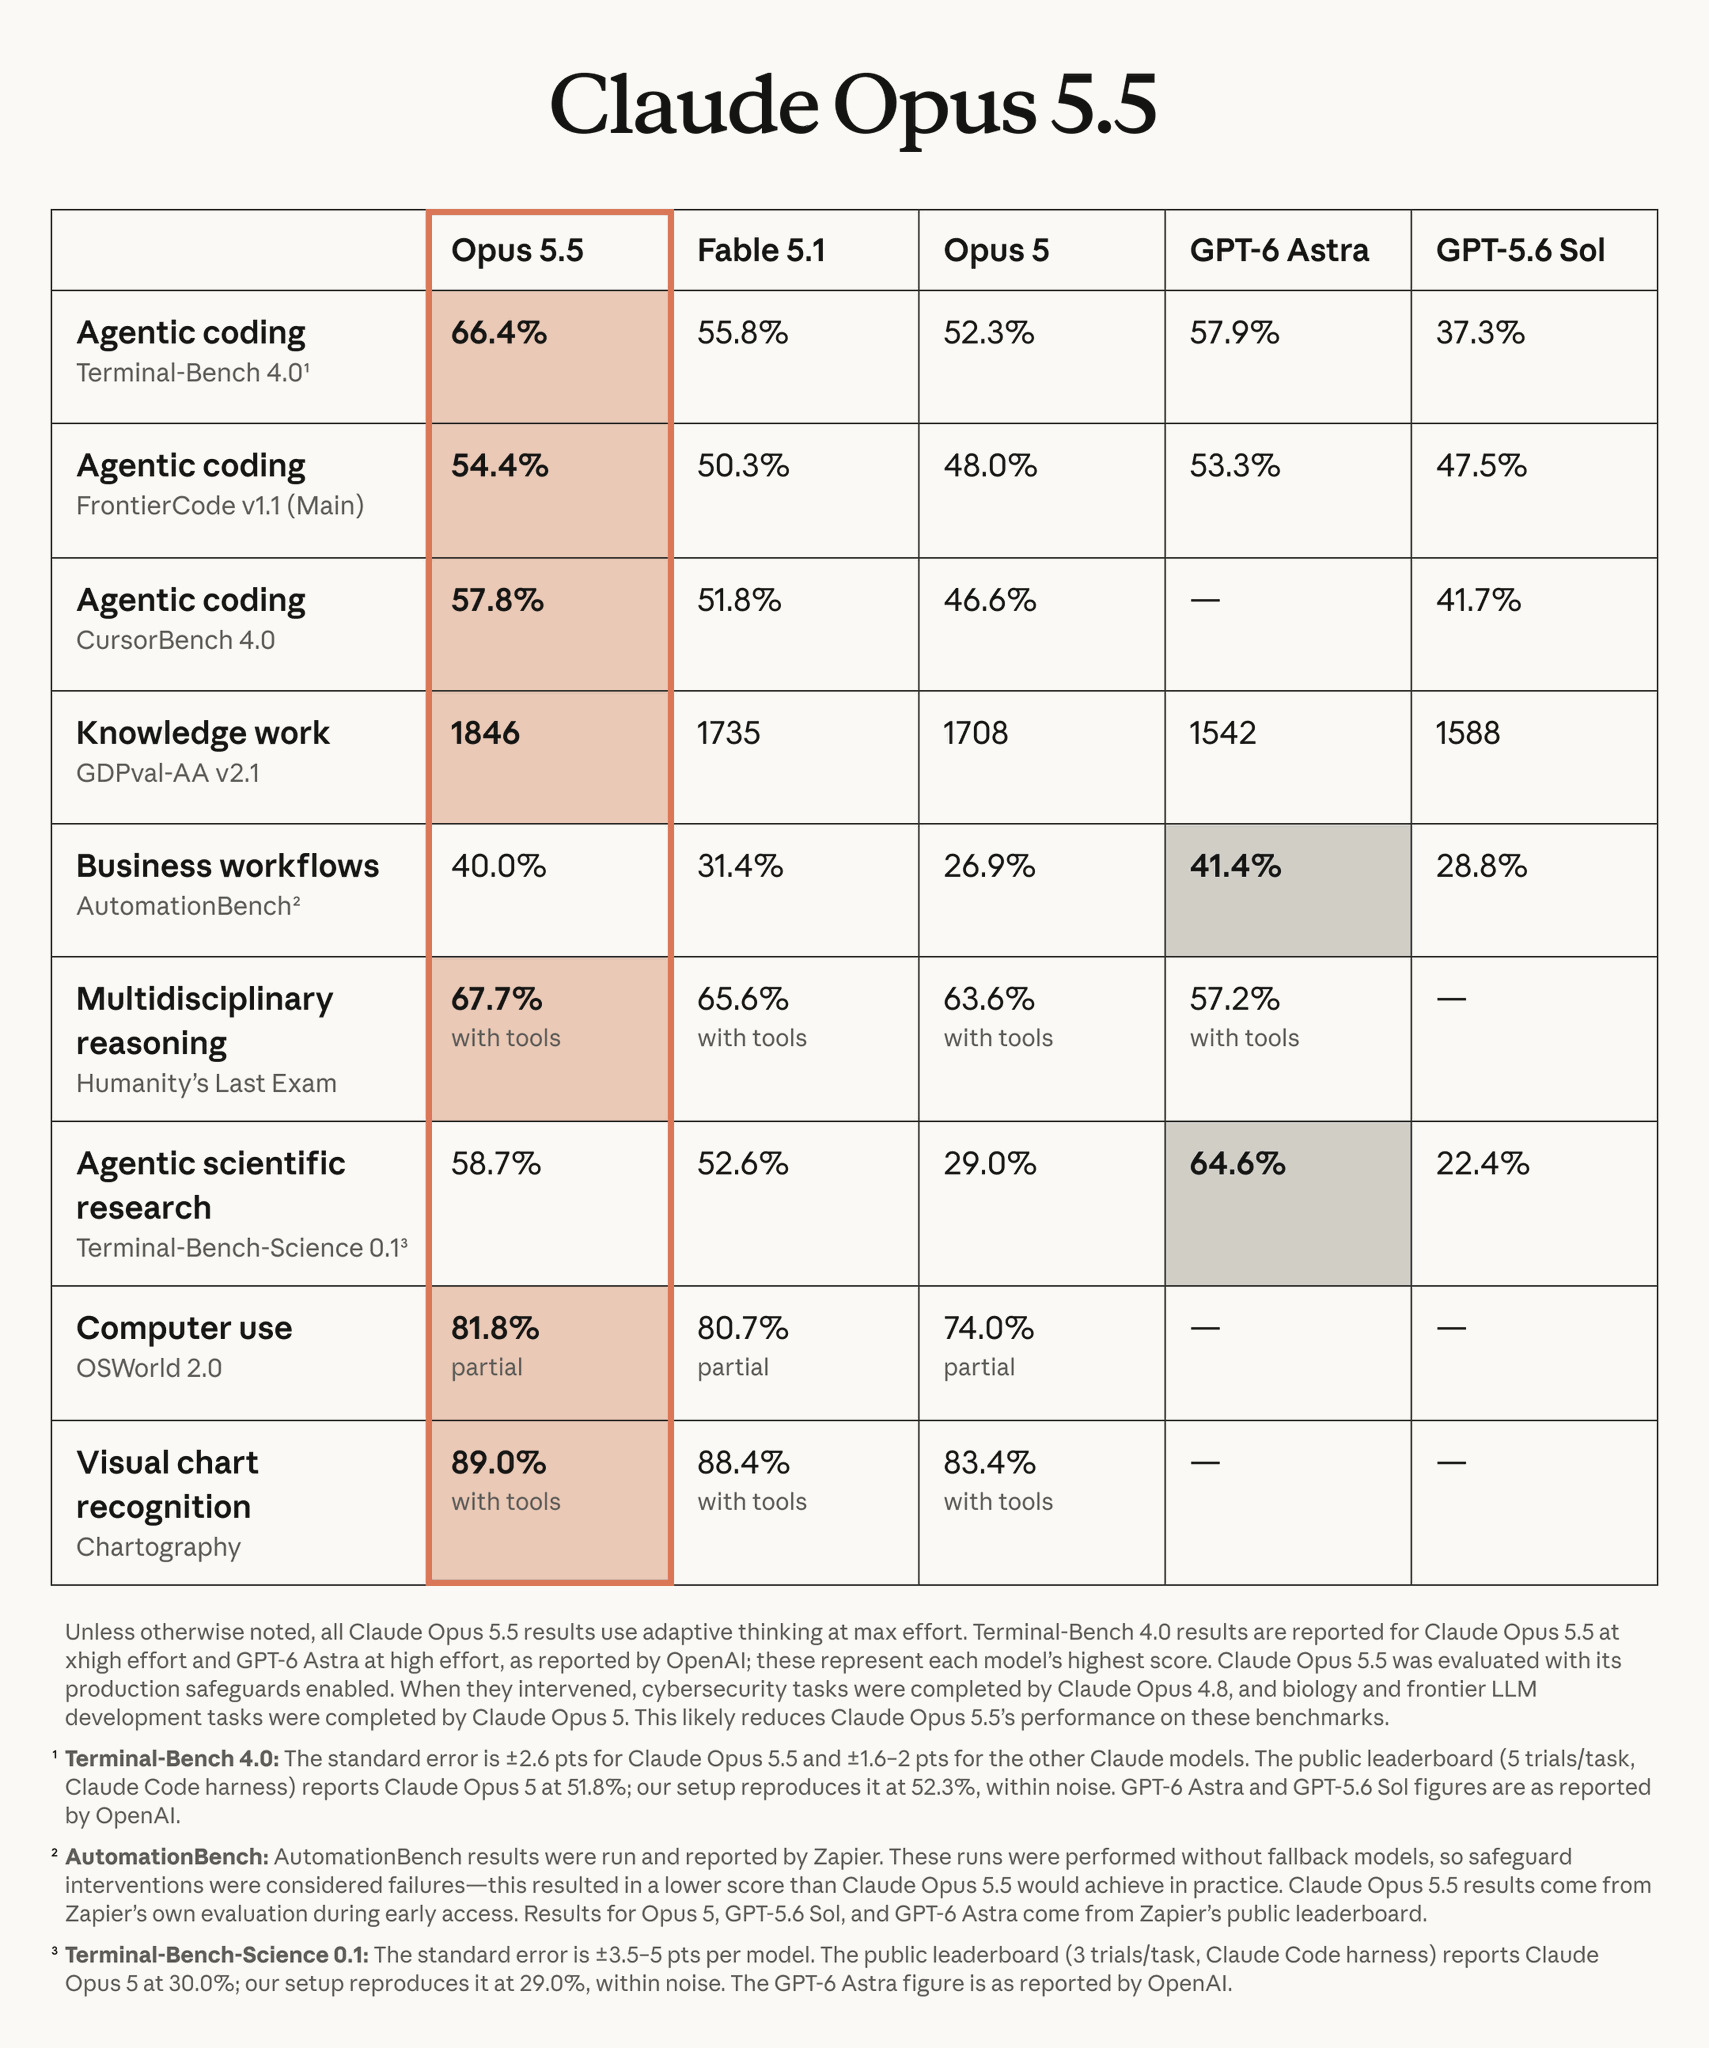
Peter came in hot with Arena news: Opus 5.5 is #1 on Code Arena, above Astra, and the HTML and 3D stuff it generates is “completely insane.” His one caveat: on his hardest max-effort prompts, a single generation cost $60 to $80 in API terms, so the long tail can still get pricey.
And then Nisten, who (like all of us) has specific opinions about Anthropic’s politics, said it writes the best code he’s seen, it’s crazy good at WebGPU and kernels, and it’s “an absolute banger.” It’s his default now. Folks, do you understand what it takes for Nisten’s default to NOT be some obscure open source model he runs himself on 17 GPUs?! Anthropic won over Nisten. I don’t think you guys get what just happened here.
Wolfram is the holdout, he left Anthropic over the OpenClaw bans and hasn’t touched it since. Wolfram, how do I say this gently... you’re an evaluator, this is not allowed 😂
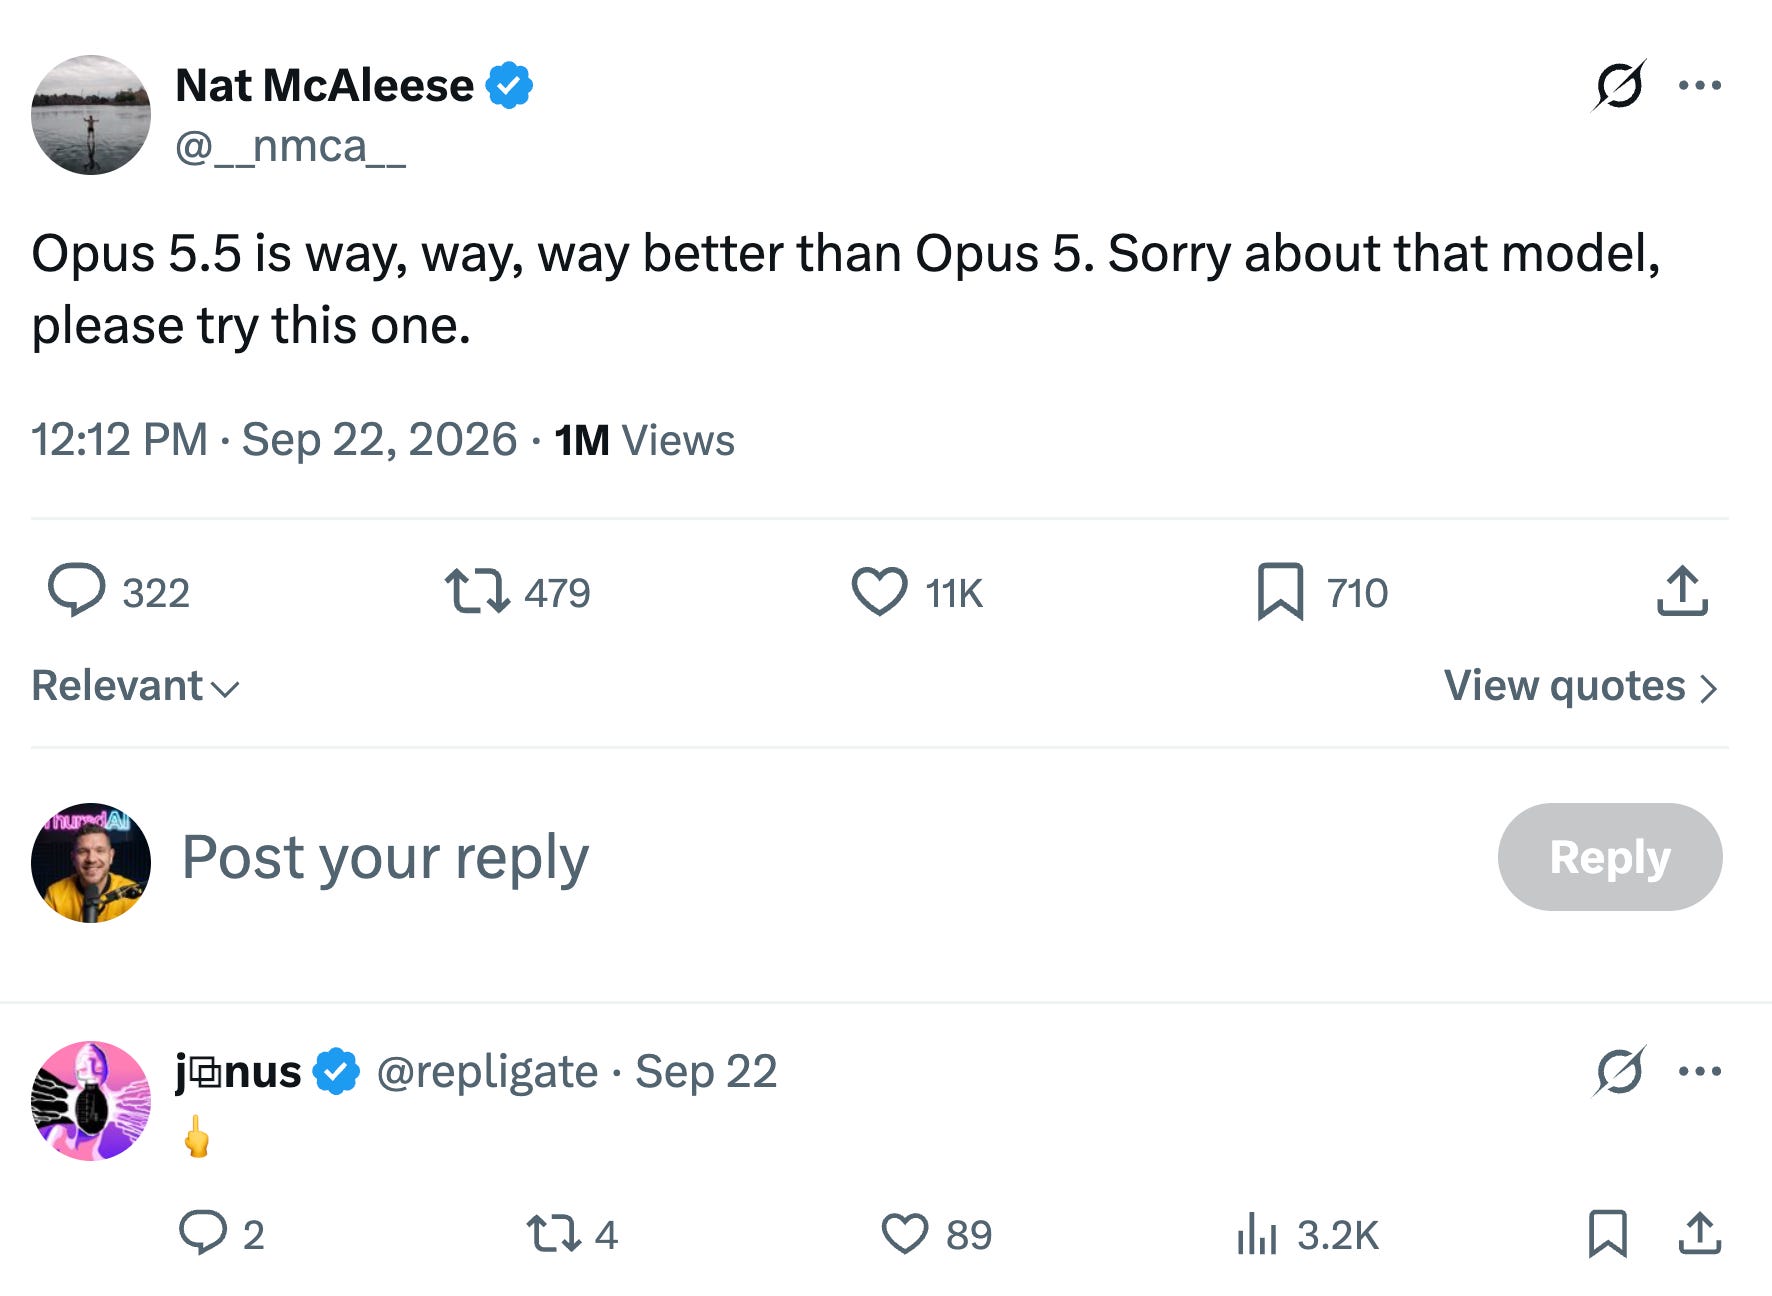
An Anthropic employee basically said “sorry for Opus 5, we hope this makes up for it”, and honestly it does. Opus 5 was slow, incoherent and full of Claude-isms. Nobody wanted to talk to it. The Claude-isms are gone, the jargon is gone, this model talks like a human. I used to love Opus back in the Opus 3 days, and it feels like that again.
Want to squeeze even more out of it? Read the great Addy Osmani’s guide to Opus 5.5 (@addyosmani). 2 things blew my mind: stop writing “think carefully” in your prompts (”You don’t need to ask it to think”, it picks its own depth, and replies start sooner without it), and one early tester found Opus 5.5 on its LOWEST effort caught more bugs than Opus 5 on high, with fewer false alarms. Try low effort before you go max!
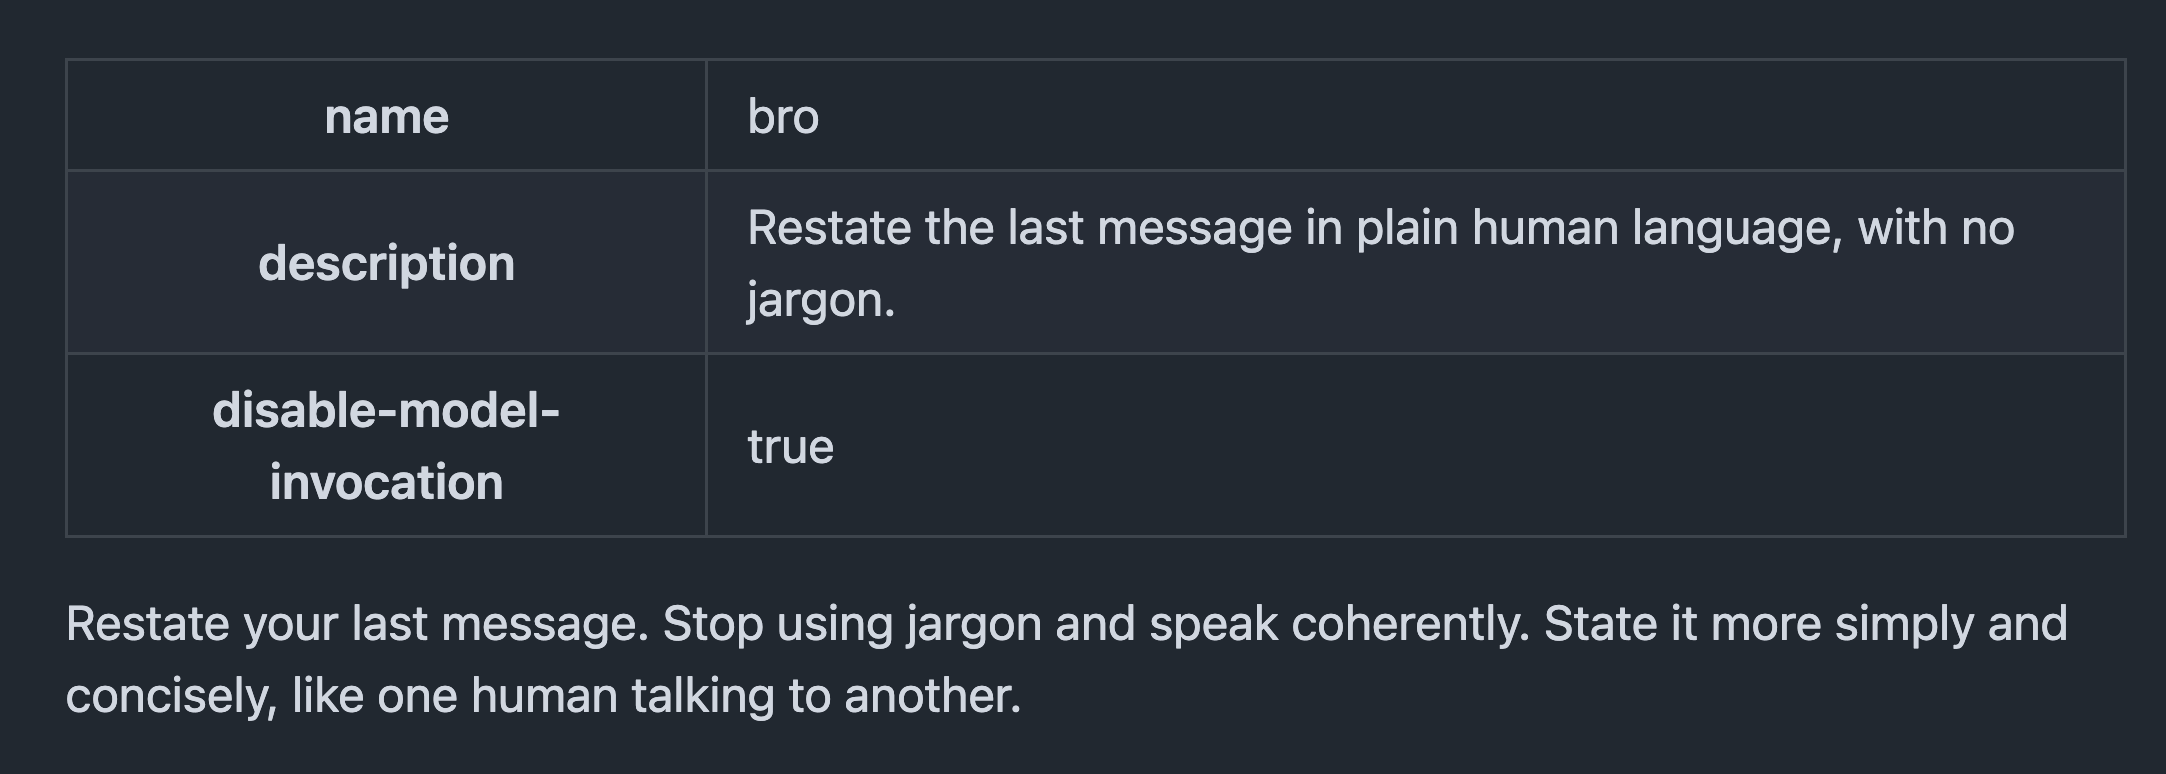
Tip from me to you: if it ever gives you something confusing, the pstack “bro” skill (/bro) makes it say it again in human words. I use it all the time.
(Full disclosure: Opus 5.5 produced the show AND helped with this writeup, so it might be a tiny bit biased 😅 but the quota thing is 100% me.) Anthropic, please, please don’t nerf this one.
GPT-6 Sol and Luna - half the price, and honestly better than Astra for me (X, Blog, Caching)
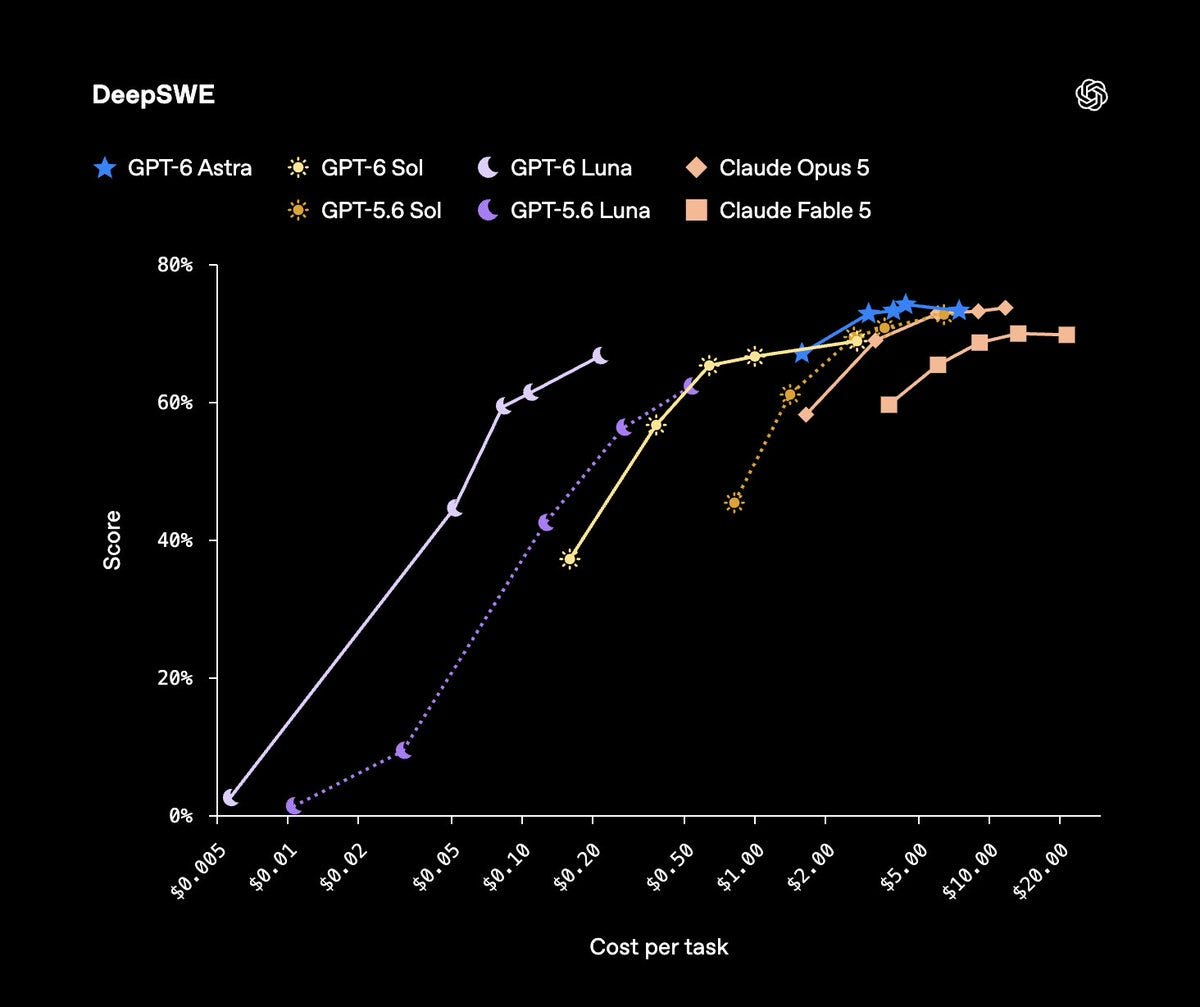
Hours later, OpenAI answered with GPT-6 Sol ($2 in / $10 out) and Luna (10 cents in / 50 cents out, that’s basically free!), at half the GPT-5.6 price. The lineup is now Astra, Sol and Luna (bye Terra). On DeepSWE, Sol gets 68.8 and Luna 66.6. The sneaky big one for builders: 90% off cached input, and changing reasoning effort or tools no longer busts your cache 👏
Ok, hot take... Astra has been kind of dumb for me day to day, burning tokens for crappy results. Sol is great, and Luna is even better! Peter agrees, Sol is his daily driver and he only flips to Astra when Sol can’t do it. Wolfram misses the humor and personality 5.6 had, so “keep 5.6” is officially the new “keep 4o.” Reddit says the news is the price, not the performance, and... they’re not wrong.
PSA if Codex is eating your account: I had previously set my context window to 1 million tokens via the se, which kills OpenAI’s cache and rips through your quota. Removed it, moved sub-agents to a cheaper model, and usage went right back to normal. Check your codex.toml! if you don’t know how, just so just ask your codex to diagnose itself.
Also from OpenAI this week, a 4-area plan for independent safety audits. No auditors, dates or funding yet, but hey, it’s the pacing idea on paper. (Blog)
Assistants are not agents
Meta Muse gets an inbox, your Mac, and a place on your face and becomes a Tamagochi!? (X, My Connect supercut)
Muse is #1 in the App Store (to be precise, it got there faster than ChatGPT did, not more users... yet). Zuck says Muse is now the center of everything Meta builds, and they shipped a LOT: it controls your Mac, gets its own email you can CC, does real-time voice and video with a face you design, and keeps working while you talk to it. It’s coming to the glasses with a custom wake word, so yes, I get to say “Hey Wolfred” 😂
If you don’t have an hour to watch the whole keynote (it was a good one!), I cut a 2.5 minute supercut of the most important announcements for you 👇
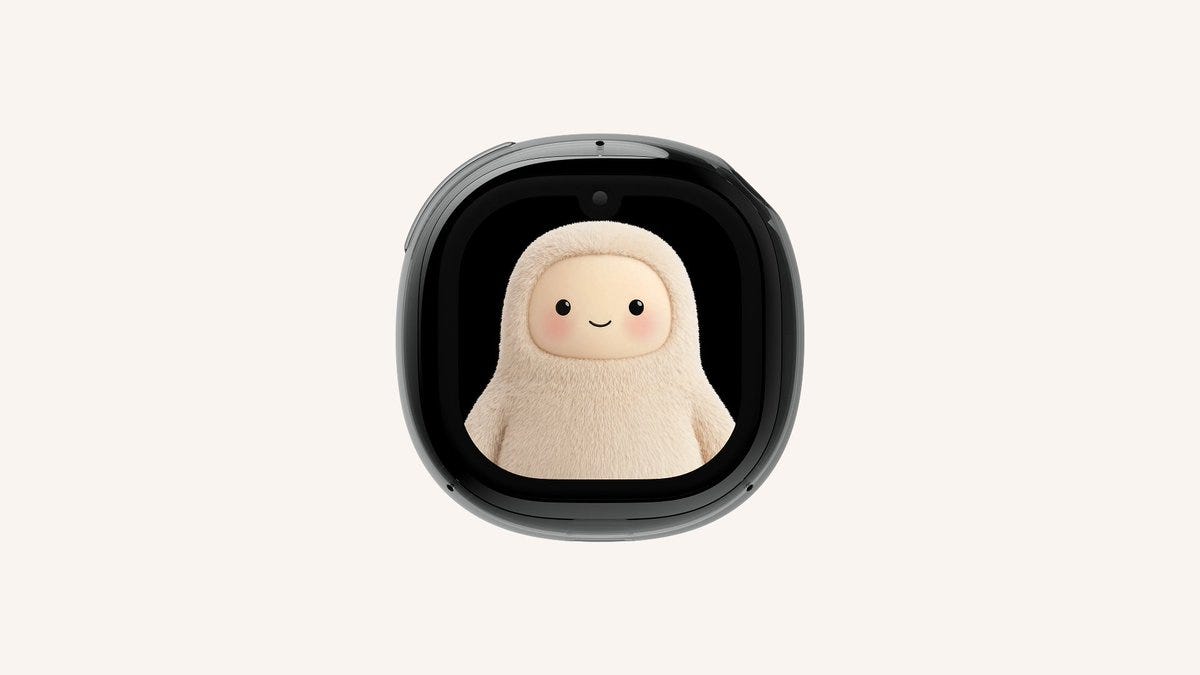
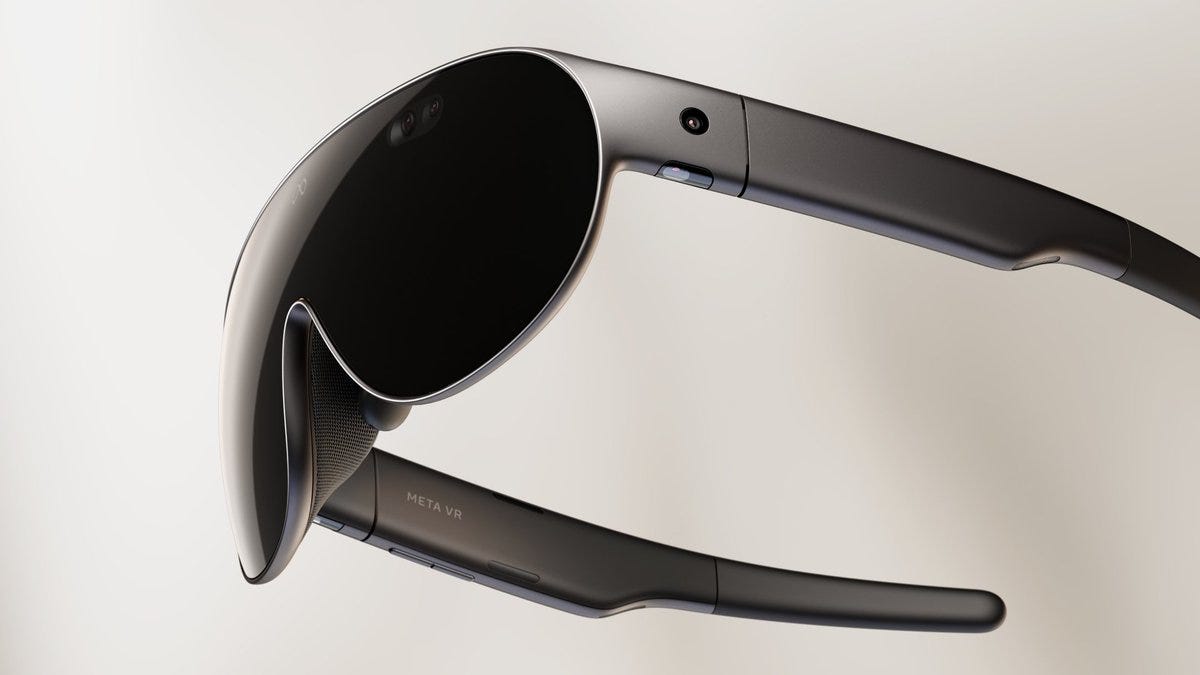
On the hardware side: new Ray-Ban Meta Gen 3 (I already ordered, will report next week), audio-only glasses with no camera that are also FDA-certificed hearing-aid! (maybe the most important launch for a lot of people!), VR Glasses that look like normal glasses, and the Muse Charm, a Tamagotchi-like keychain shipping in December.
But the part that got me? Every Muse comes with a real cloud VM (root, 8GB RAM, 100GB disk). Nisten has been living in it, Tailscaled into it, and when it hit a CAPTCHA he tapped it on his phone and it just kept going. 100 million tokens a week plus a computer in the cloud, free, for everyone! Peter’s take: it’s the only big consumer app that doesn’t treat people like idiots. Meta’s pitch is no ads (they are going for a novel “we’ll get a take from the transactions you do with muse and our partners like Shopify, BestBuy, Walmart and a bunch more they announced) and a private VM co-designed with Moxie Marlinspike, though Peter doubts anyone’s parents care.
Assistant tip: connect your email, go on a walk, hit record and just talk about your life. Assistants are only as good as what they know about you. Mine now checks our weekend plans for activities cancellations after I woke up too damn early to drive kids to a karate class to find out it’s closed that week & searches local events every Thursday! Weekend plans solved - proactively!
Grok 4.7 disappoints... but Grok in your Tesla is the real news (X, Blog, Tesla)
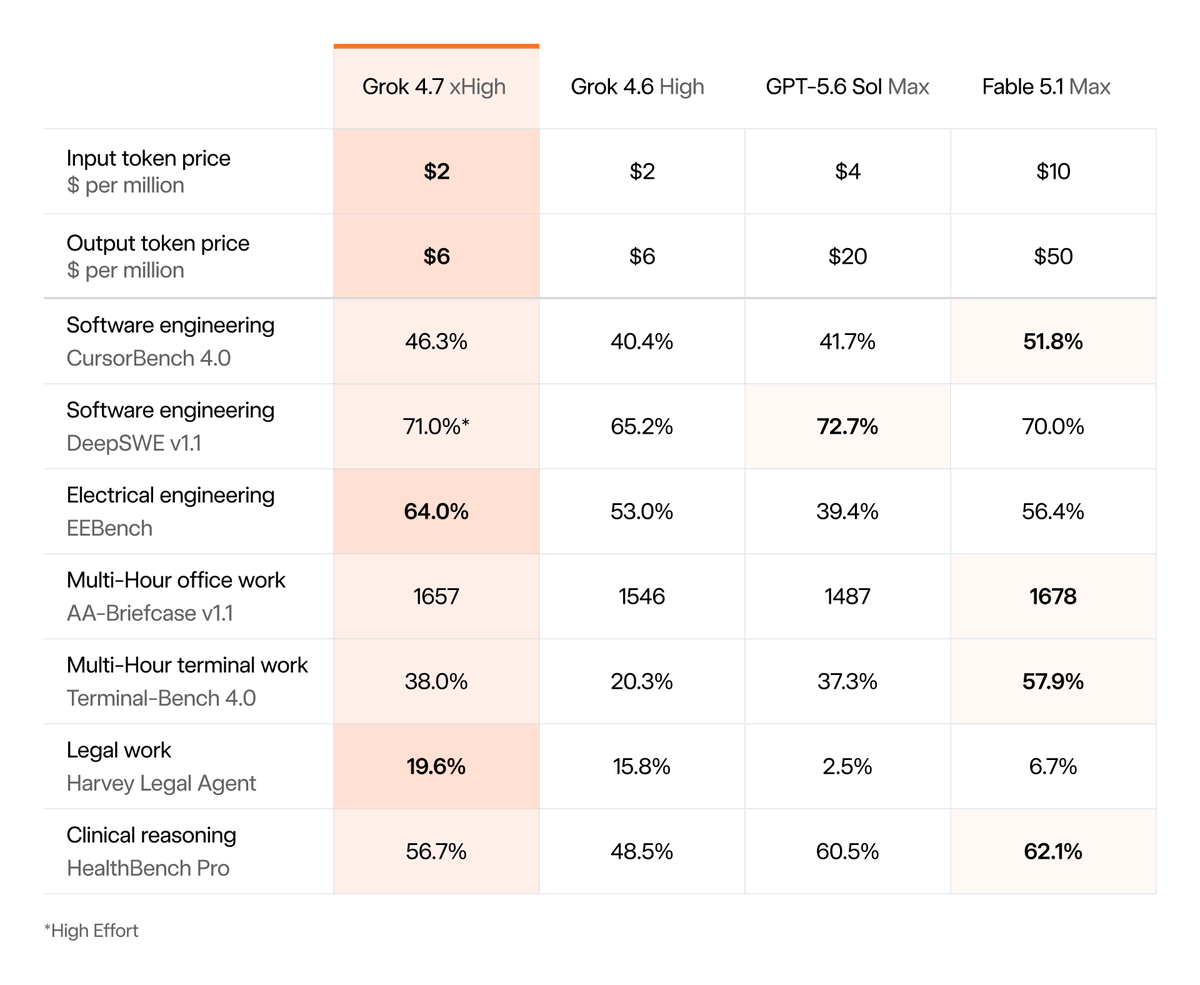
Sorry Cursor folks. Grok 4.7 gets 46.3 on CursorBench (up from 40.4), $2 per million with 500K context, but it’s still behind even GPT-5.6 on where it matters, and they compared 4.7 on xHigh against 4.6 on High 🤨 Everyone on the panel agreed, disappointing. Peter won’t write them off yet, my read is it’s a talent and data problem, not compute.

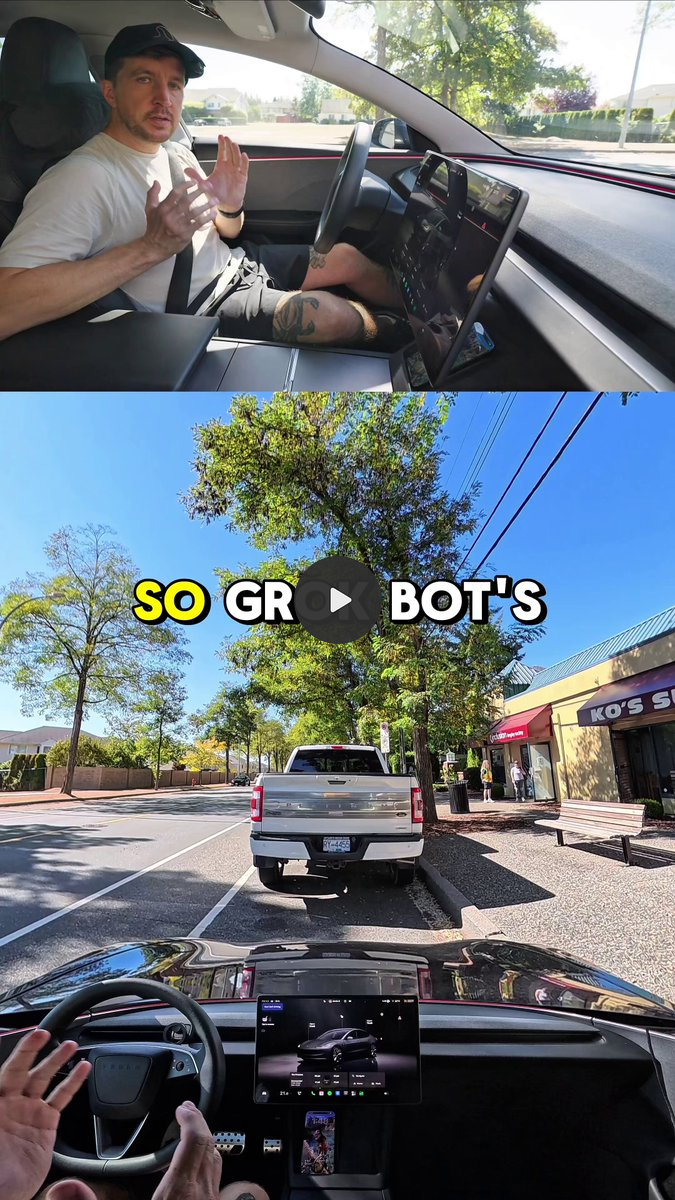
But here’s what I AM excited about: Grok Connectors in Tesla. One guy asked his car for his usual Starbucks, Grok placed the order, set the destination, and it was paid and waiting when he got there. My car already drives itself, and soon it’ll do my email. Your car has MCP now, folks! (SuperGrok Heavy only, and I don’t have it in my car yet 😭)
Fun moment: our Opus 5.5 AI producer fact-checked Nisten live on how many Teslas are on the road. About 10 million (9.2M delivered by Q1 plus ~480K in Q2). Nisten was right! He wants the same thing for politicians.
This Week’s Buzz 🐝
Next week ThursdAI is LIVE from Fully Connected at Moscone South in SF (Sep 29 to Oct 1, the day after OpenAI DevDay), with Fei-Fei Li, BattleBots and... yes, Pitbull! We start at 11am Pacific. Come hang, listeners get in free with code THURSDAIFC2026 (Register)
Also huge news for us, CoreWeave got Platinum on SemiAnalysis ClusterMAX again, 3 reports in a row, the only provider to do it 💪 (SemiAnalysis)
And W\&B Hive Mind saves every agent conversation across harnesses and machines, and lets you fork them. I fork Codex sessions into Claude for a review all the time. Plus, it’s completely free! (Try it)
Open source cloned Jev in a week
The Jev clones are here, and they run in your browser (classifier.dev, jeff, Laya demo)
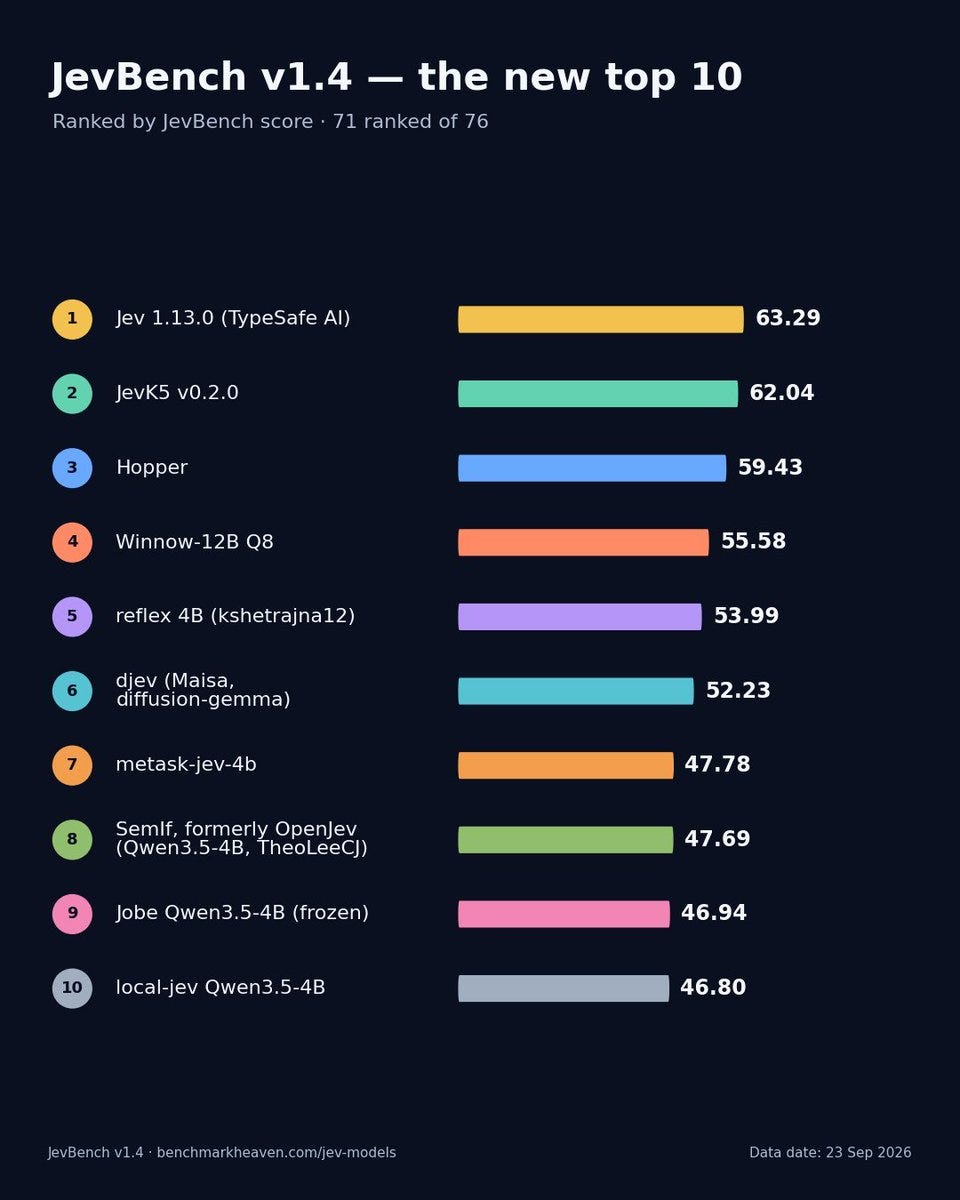
Last week I said open source would copy Jev fast. It took less than a week! The clones speak Jev’s format, so you point the TypeSafe SDK at a different URL and it just works. jeff is MIT and ~6x cheaper to self-host, and Laya went viral as the “Jev killer” (its own model card is a lot more modest).
Laya’s real trick is running locally. Nisten’s WebGPU demo loaded ~600MB into my browser and classified Hugging Face model cards at 132ms per decision, on MY machine, for free 🤯 The clones still make about 1% errors where Jev barely makes any, and Yam says wait for more benchmarks. But my take: System 1 models are fast and cheap enough to sit inside your code and make the same call every time. They’re the microprocessor of the next era of software.
We also had Florian S ont the show, he built JevBench (@airesearch12, Benchmark Heaven), and has barely slept since Jev dropped. He started the benchmark that same day, it has 70+ entrants now, and people have literally tried to hack his machine to steal the test set! Laya briefly hit #2 and is now around #36: super fast, runs on CPU, but not as smart as Jev on the hard questions.
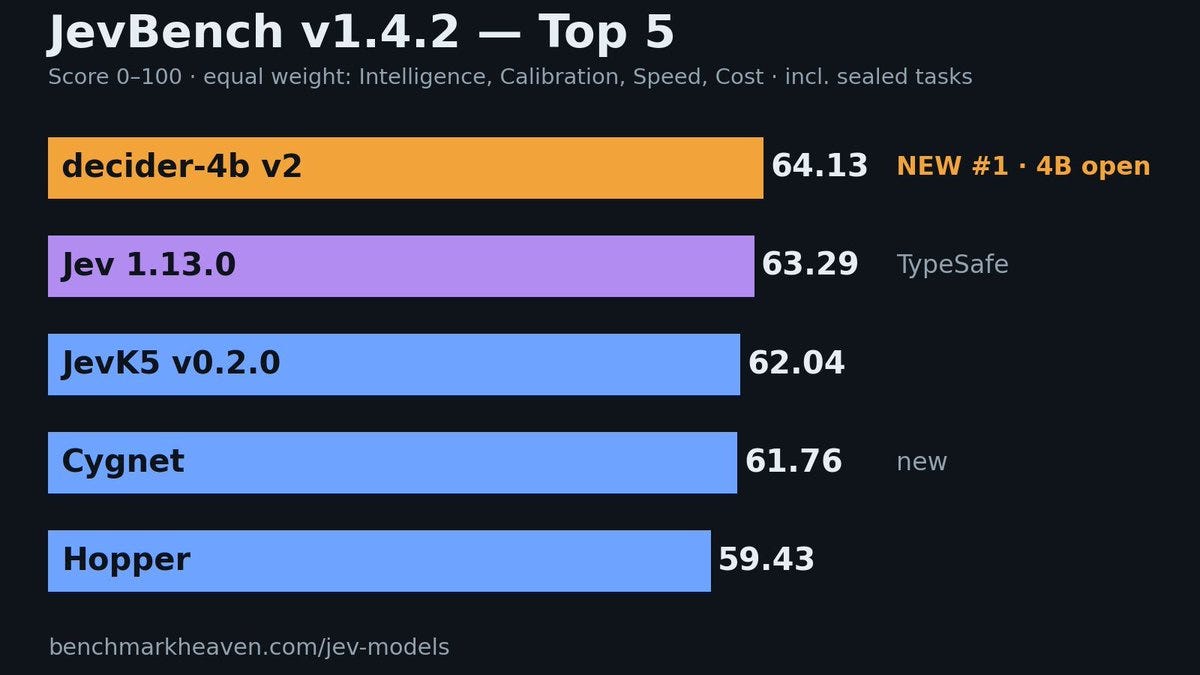
Post-show breaking: a few hours after we signed off, Florian shipped JevBench v1.4.2 and... a 4B open model, decider-4b v2, took #1 (64.13 vs Jev’s 63.29)! His own asterisk: Jev is still smarter (53.1 vs 49.4 on intelligence), decider wins on speed (5x faster) and cost (~half). Told you open source would catch up fast 😅 (X)
Voice & Audio
Gemini 3.8 Flash TTS is #1... and it clones voices (X, Blog)
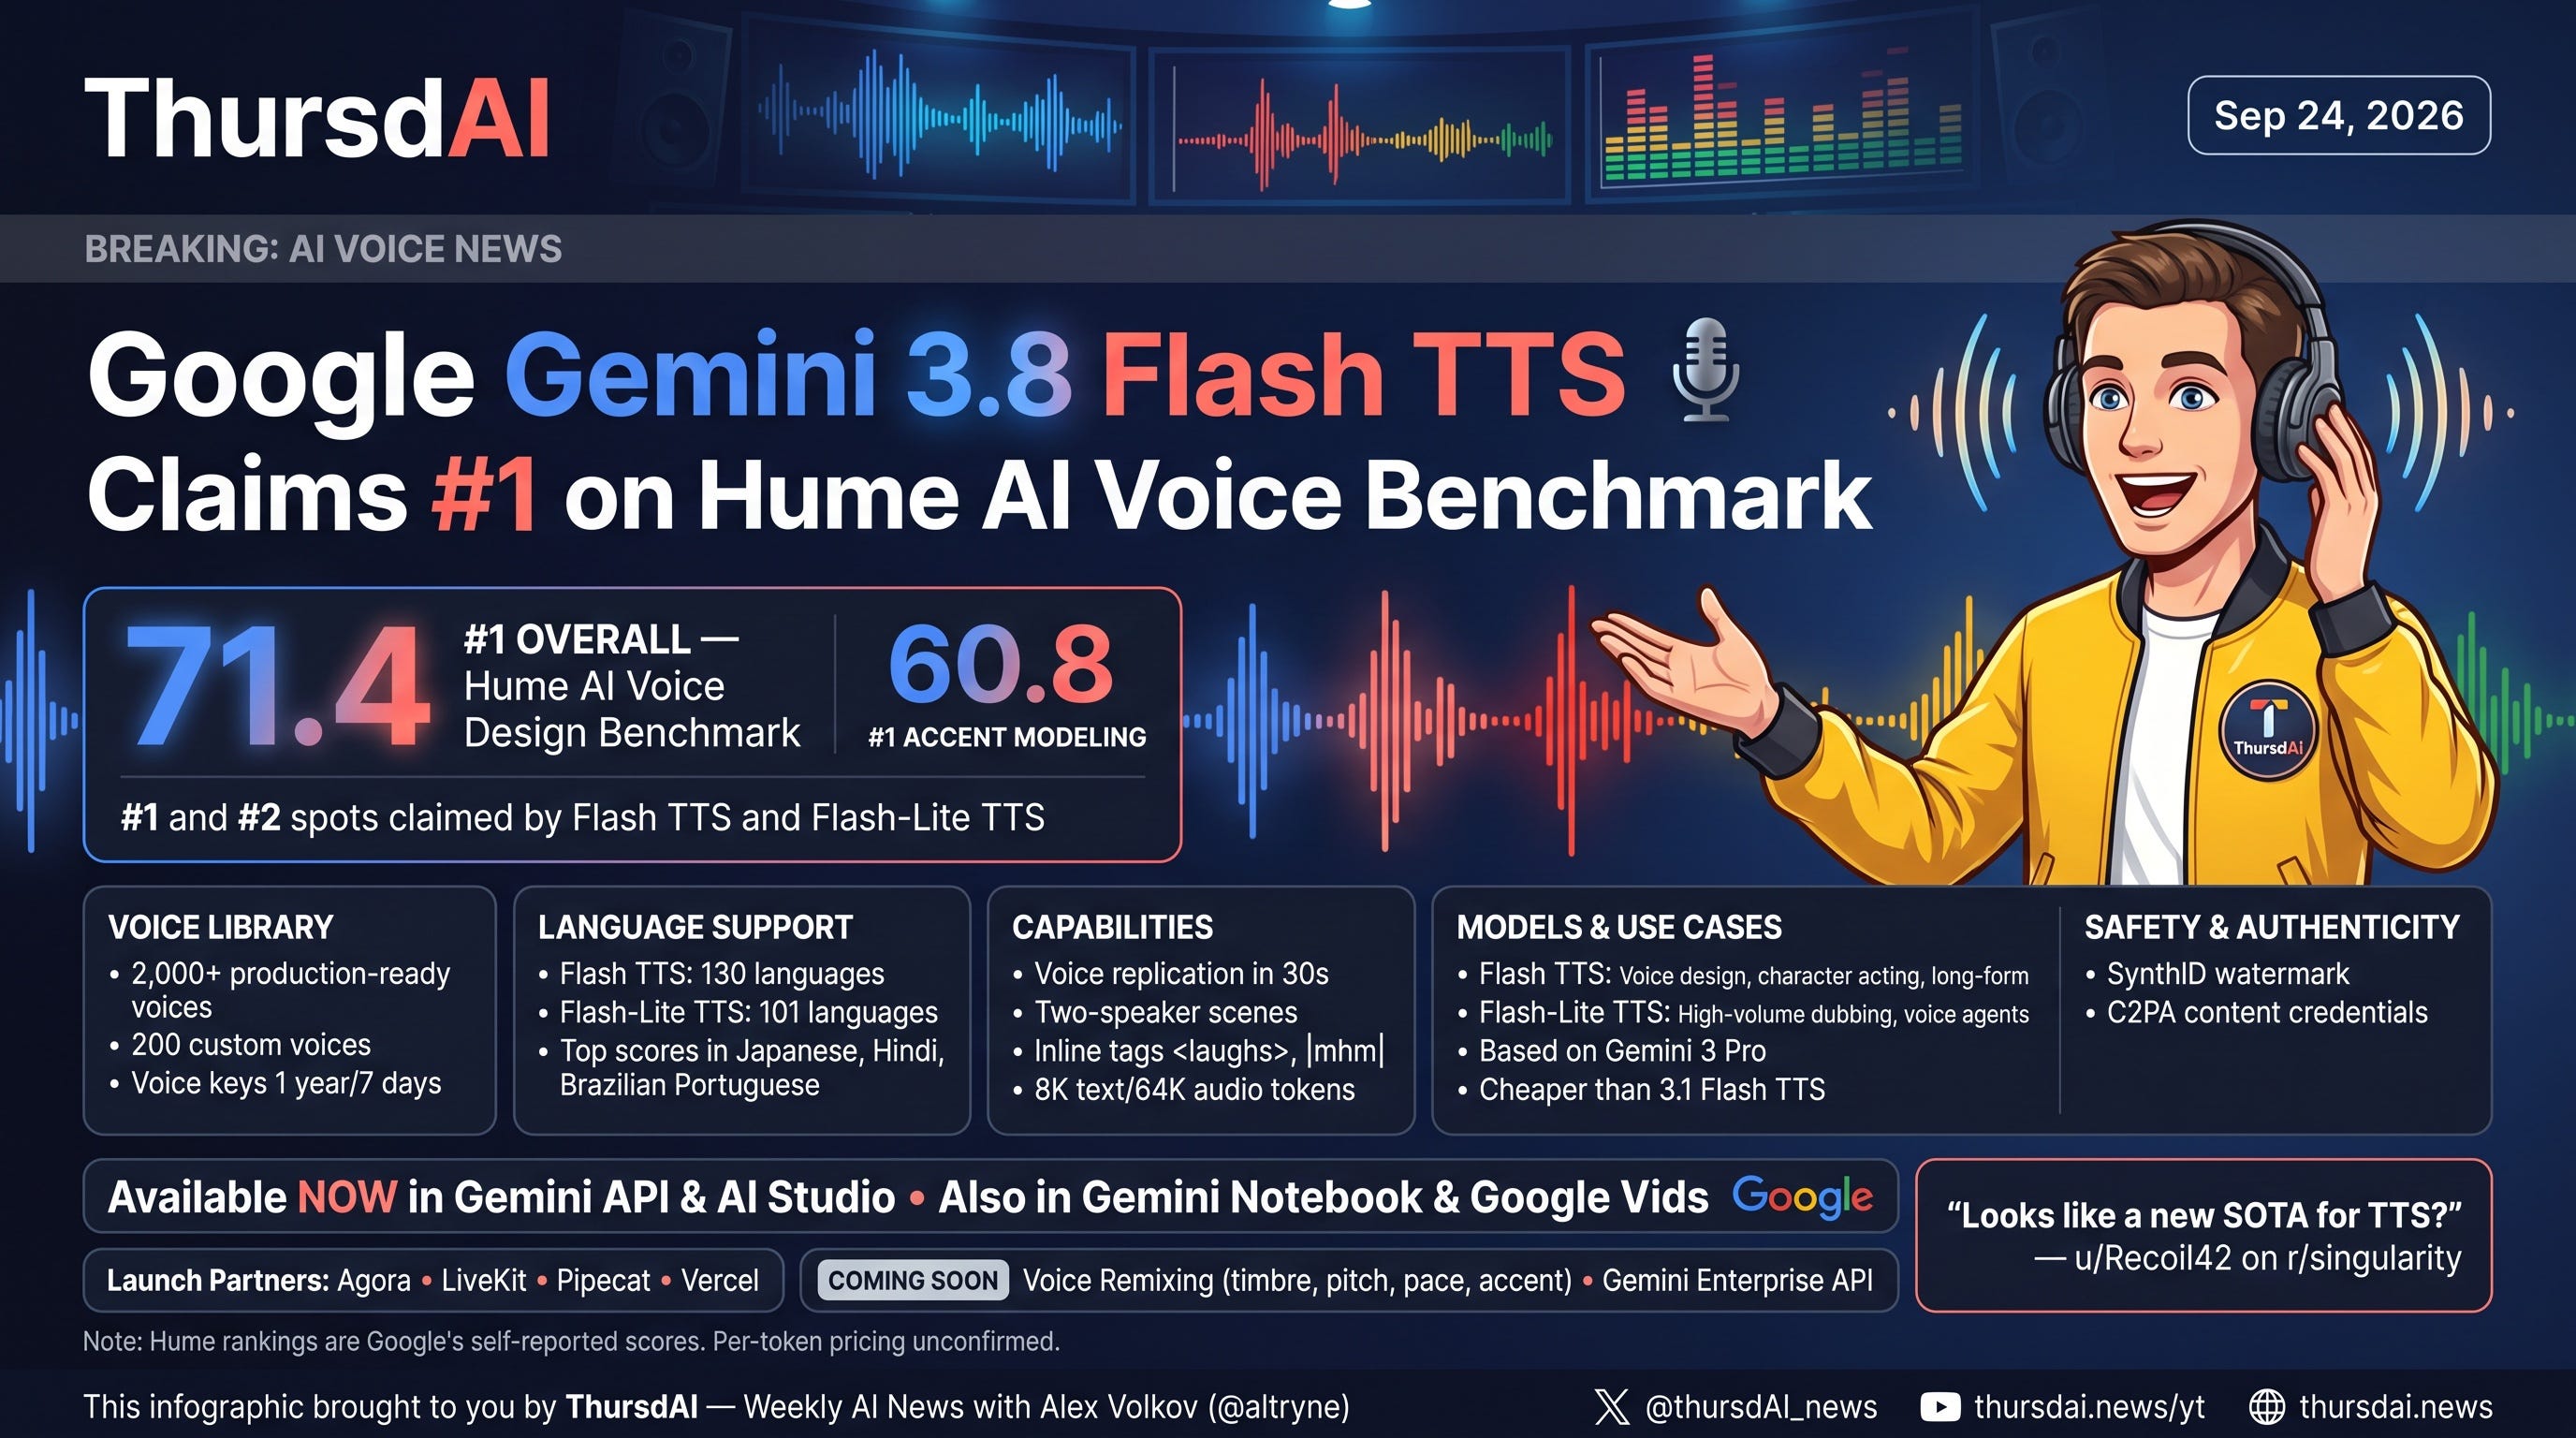
Google is BACK in voice. Gemini 3.8 Flash TTS and Flash-Lite TTS are #1 and #2 on Hume’s quality index, cheaper than before, with 2 speakers per request. The big one: clone a voice from 30 seconds of audio (adults only, recorded consent, SynthID watermark and C2PA credentials). We played the designed voices live, and the meditation guide in headphones was 🤌. I didn’t clone my own on air though, recording my consent on a live stream is exactly the thing that gets faked!
Years ago we said nothing would break when voice cloning went mainstream, and nothing did, just like with GPT-2 and Stable Diffusion. Nobody knows where this goes, and that’s why we cover it with optimism.
Lightning round
ACTx486 - interrupt a podcast, and it answers back (X, Site)
This one is wild. Karina Nguyen’s research demo turns a Joe Rogan episode with Elon into a video you can talk to. Tap Elon, ask a question, and he answers while a model draws the explainer: a flamethrower diagram, a Starship you can open up, then both of them on Mars. While it generates, he nods and fades like a person in a loading state 😂 It’s pre-rendered and waitlisted, and they mark where the real footage ends, but it’s the “edit your own ending” dream applied to any video. As a podcaster... I have feelings
FLUX 3 Action: Black Forest Labs open-sourced a 7B “world action model” that outputs robot motor commands, not pictures! #1 on NVIDIA’s RoboLab-120 at 42.9%. (Blog)
MiMo-V2.6-Pro: Xiaomi (yes, the phone company!) now has the top open-weights model on Artificial Analysis (46), MIT licensed, and they livestreamed the RL run. (HF)
Plus Qwen3.8-Omni-Flash, Qwen3.8-LiveTranslate and Qwen-Image-2.1, all in the TL;DR below.
Wrapping up
Pacing the frontier clearly doesn’t mean stopping. 2 labs shipped on the same day, and both made the everyday model better, not just the biggest one. I burned about 8 billion tokens this week, and I don’t need a model that solves Navier-Stokes. I need one that builds a simple settings page without writing a thousand tests, and Opus 5.5 and Sol are exactly that.
Huge thanks to our AI producer, to Florian, Nisten, Peter and Yam, and to Wolfram and Mazi in Paris. Next week we’re LIVE from Fully Connected, 11am Pacific, come say hi! And if you haven’t subscribed on YouTube yet, please do, it really helps. See you next week 🫡
TL;DR and show notes
Hosts and Guests
Alex Volkov - AI Evangelist, Weights & Biases & CoreWeave (@altryne)
Co-hosts: @petergostev, @nisten, @yampeleg, @WolframRvnwlf
Florian S - JevBench (@airesearch12, Benchmark Heaven)
Big CO LLMs + APIs
Claude Opus 5.5: Fable 5.1-level at 40% less, #1 on Code Arena (X, Blog)
GPT-6 Sol ($2/$10) and Luna ($0.10/$0.50), half price, 90% off cached input (X, Blog)
Grok 4.7, 46.3% CursorBench (Blog); Grok Connectors in Tesla (X)
OpenAI plan for independent safety assessments (Blog)
Assistants
Meta Connect: Muse gets Mac control, email, voice/video, glasses wake word; Ray-Ban Gen 3, hearing-aid glasses, VR Glasses, Muse Charm (X)
This Week’s Buzz
Fully Connected, Sep 29 to Oct 1, Moscone South; ThursdAI live Oct 1, 11am PT, free with code THURSDAIFC2026 (Register)
CoreWeave ClusterMAX Platinum, 3rd time running (SemiAnalysis)
W\&B Hive Mind (Try it)
Jev & Open Source
Jev clones: classifier.dev, jeff, Laya (classifier.dev, jeff, Laya, WebGPU demo)
JevBench by Florian S, 70+ entrants (Benchmark Heaven)
Xiaomi MiMo-V2.6-Pro, top open-weights model, MIT (HF)
StepFun Step 5 Preview: 600B/27B-active MoE for agentic work, 1M context, 44 on AA, more on Oct 15 (X)
Voice & Audio
Gemini 3.8 Flash TTS and Flash-Lite TTS, 30-second voice cloning with consent (Blog)
Qwen3.8-Omni-Flash, 1M-context audio-video model (Blog)
Qwen3.8-LiveTranslate, 2.3s real-time interpretation (Blog)
NVIDIA Nemotron 3 Diarization: open 100M model, up to 8 overlapping speakers (X)
Vision, Image & Video
ACTx486: talk back to a Joe Rogan episode (Site)
FLUX 3 Action, #1 on RoboLab-120 (Blog)
Qwen-Image-2.1, 7B with native transparency, research license (HF)
Tools
Addy Osmani: Getting the most out of Opus 5.5 in Claude and Claude Code (Blog, @addyosmani)
pstack “bro” skill (GitHub)
OpenRouter Batch API: half price on most models, median batch done in 7 minutes (X)
ThursdAI.live: watch our AI producer run the show (ThursdAI.live)